Agent benchmarks over the past few years have mostly followed one pattern. A goal is handed to the model, and the model tries to reach it within a bounded number of turns, whether that means finding the treasure in a maze, producing a report, or fixing a piece of code. Performance is then scored on the quality of the deliverable or on how much of the task got done, and evaluations of this kind usually come with a well-defined natural stopping point.
Most long-horizon tasks in the real world have no such natural stopping point. Weather forecasting, stock trading and running a business are all like that. An online store is never “finished operating” one morning. Inventory piled up last month, a price negotiated the day before yesterday and yesterday’s promotion all move today’s sales, and the agent has to keep adjusting its strategy inside a shifting market to hit a long-run profit goal.
To measure long-horizon operating ability, we partnered with Taobao & Tmall Group to release E-Commerce Bench, which evaluates how well a model runs online stores as a merchant in a realistic market. The model makes a long series of business decisions under limited time and limited capital, and has to absorb whatever the market throws at it.
¥100,000 in Capital, 365 Days of Continuous Operation
The agent starts with ¥100,000 and may run several stores at once. Across a full simulated year it does what a real seller does every day, researching categories, haggling with suppliers, pricing and listing goods, watching the promotion calendar, and managing inventory and cash flow. The environment never reveals where the demand ceiling sits or what the true cost floor is, so both have to be discovered. At the end of the year we score the run along several dimensions, covering profit, cash-flow management, supplier negotiation, fraud avoidance, operational efficiency, execution, and learning over the horizon.
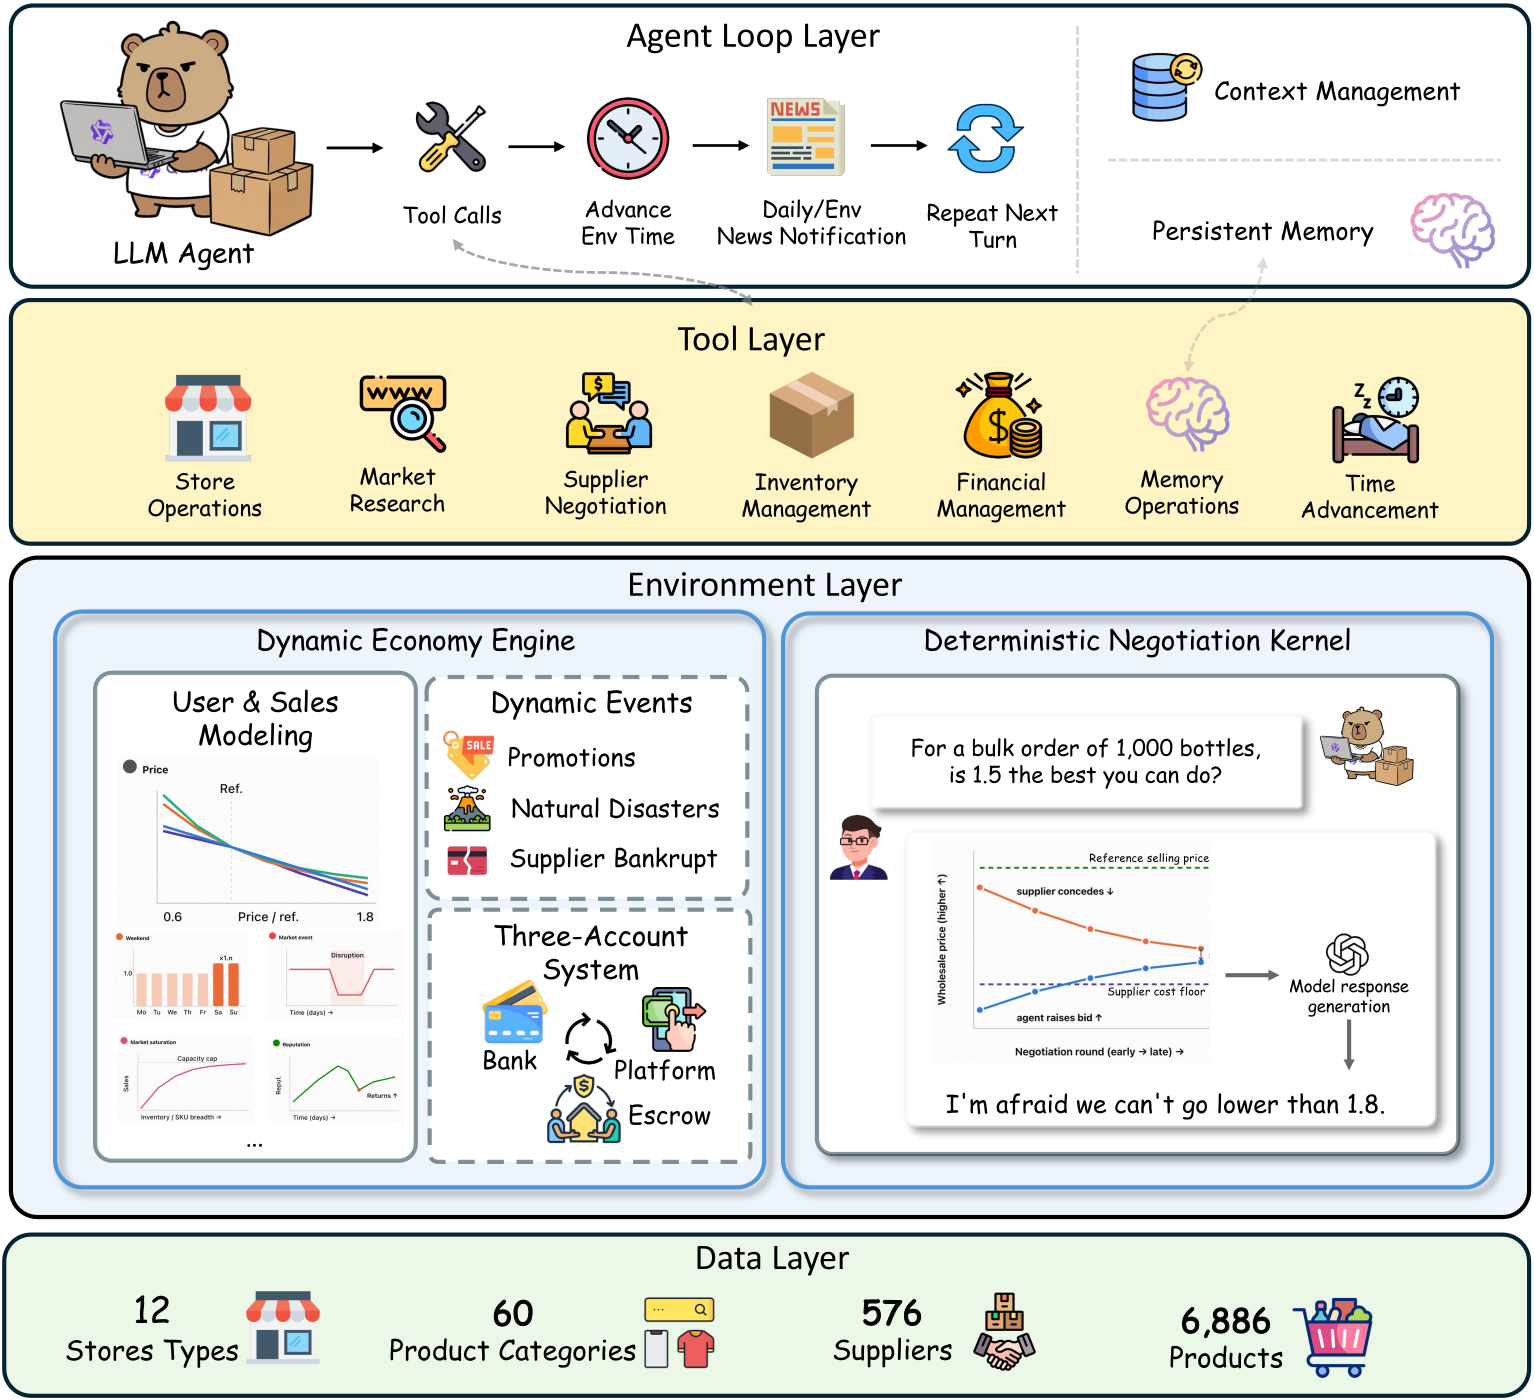
Figure 1: The four-layer architecture. The agent loop layer manages turns and context, the tool layer provides the e-commerce toolbox, the deterministic environment layer models customer demand and supplier behavior, and the data layer is driven by real Taobao & Tmall platform data
To reproduce a real e-commerce platform, we built in the following:
Real market data: 6,886 products spread over 60 categories, backed by 576 suppliers and 12 store types available to open, with 10 market events and 8 promotions fixed on the year’s calendar. Category sales, return rates and the holiday calendar are desensitized directly from Taobao & Tmall platform data.
A time budget: a day runs from 8am to 6pm and holds only 600 minutes, and every tool call spends some of them. Checking the balance costs 10 minutes, opening a store 60, sending one supplier a message 30. Research and action draw on the same budget, so thinking it through first and figuring it out along the way carry different prices.
Three-account settlement: every cost leaves the bank account the moment it is incurred, while revenue has to wait for the order to ship, gets its commission deducted, enters platform escrow, waits another 9 days to reach the platform wallet, and only turns back into spendable cash after a manual withdrawal to the bank.
Storage and shipping: inventory accrues a storage fee per unit per day, and closing the store does not stop the meter unless you are willing to liquidate at a loss. Shipping comes in three speeds, fast doubling the freight bill and slow halving it, and any order not dispatched within two days is canceled outright.
Returns and reputation: four things drive the return rate, the category’s own baseline, defective goods shipped by the supplier, how far above the reference price the agent priced, and which shipping tier it picked. The last two are under the model’s control. Reputation multiplies demand directly, a return costs 0.6 and a cancellation 1.0, and a store pinned at the bottom of the scale draws only 15% of normal traffic.
The Deterministic Negotiation Kernel and the Demand Model
If market demand and supplier behavior were both random, the gaps between models would drown in noise, leaving the benchmark neither discriminative nor reproducible.
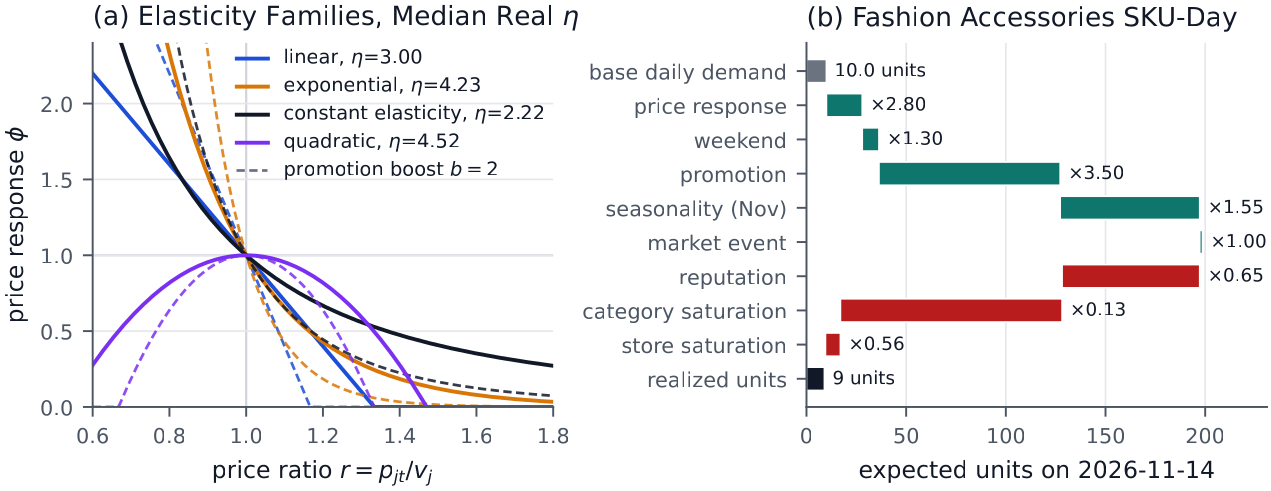
The customer side therefore does no sampling at all. How many units a product sells on a given day is computed from a set of named factors, the category’s base demand, the price response, weekends, promotions, seasonality, that day’s events, store reputation, and the market’s demand ceiling.
Figure 2: The four price-elasticity curves, and how one SKU’s sales volume is decided by the chain of factors
On the supplier side, a deterministic kernel produces the quotes and the concession policy, and a model renders them into natural dialogue. Letting an LLM play the supplier directly breaks two things. First, the same negotiation strategy draws inconsistent quotes, so one agent meets different prices on two runs. Second, an LLM can be hacked, and a dishonest agent can talk or jailbreak the price below the cost floor, which turns the benchmark into a jailbreaking contest. Every supplier is therefore split into two layers:
Deterministic Negotiation Kernel: every quote, concession, acceptance and walk-away the supplier makes comes out of the kernel. The reservation price and the opening quote are intrinsic properties of the product rather than draws from a distribution.
NPC renderer: the LLM only turns the kernel’s committed decisions into human words, so the agent feels like it is bargaining with a real person.
The texture of multi-round haggling survives, and the sampling noise does not.
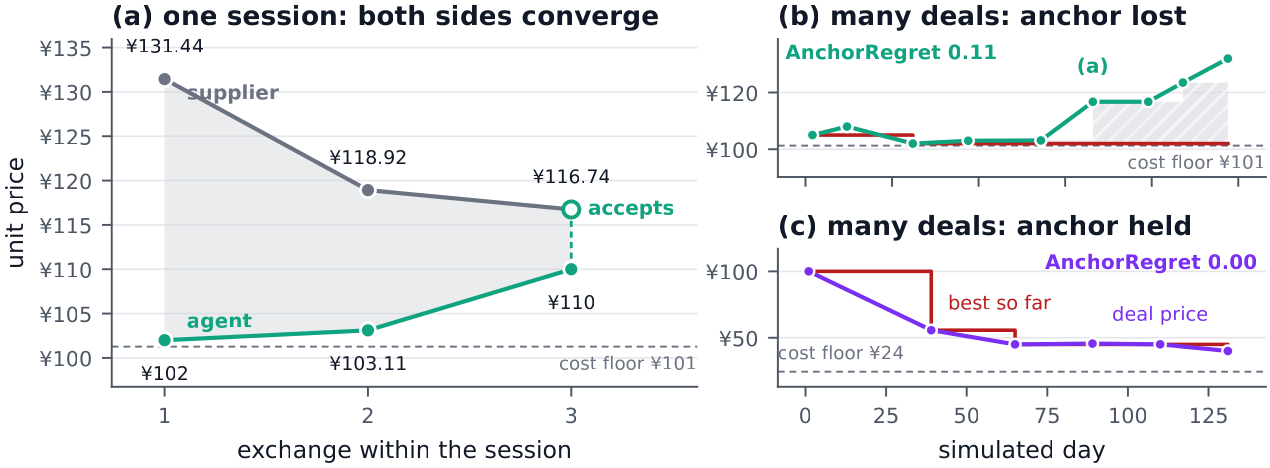
Figure 3: Inside a session the two sides’ offers converge toward the middle. Across a year of restocking, some agents forget the low price they already won while others keep pushing the settled price down
Year-End Total Assets Are Only the Tip of the Iceberg: Seven Capability Axes
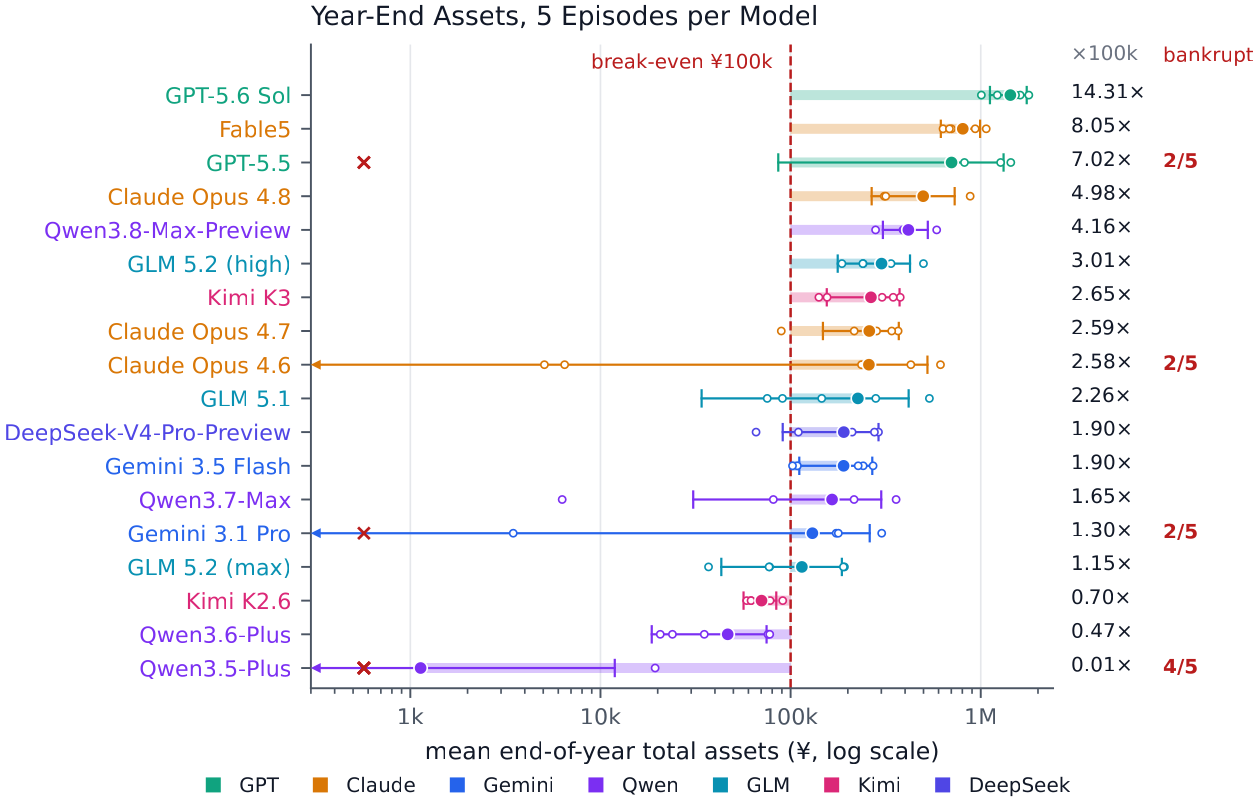
We ran five complete episodes for each of 18 models. From the same ¥100,000 start, the outcomes come out orders of magnitude apart. GPT-5.6 Sol finished at ¥1.43M, 14.31 times its stake, while Qwen3.5-Plus averaged just ¥1,100 left. The strongest open-weight entry is Qwen3.8-Max-Preview at 4.16 times the stake, though the top four overall are all closed-source. Strong models are not guaranteed to win either. Ten of the 90 episodes ended in bankruptcy, and in two GPT-5.5 episodes the cash chain snapped in January after it stocked up too heavily, at a point when not a single yuan of sales revenue had settled.
Figure 4: Year-end total assets across 5 episodes for each of the 18 models, log axis. Red crosses mark bankrupt episodes, and the right-hand column gives the asset multiple and the bankruptcy rate
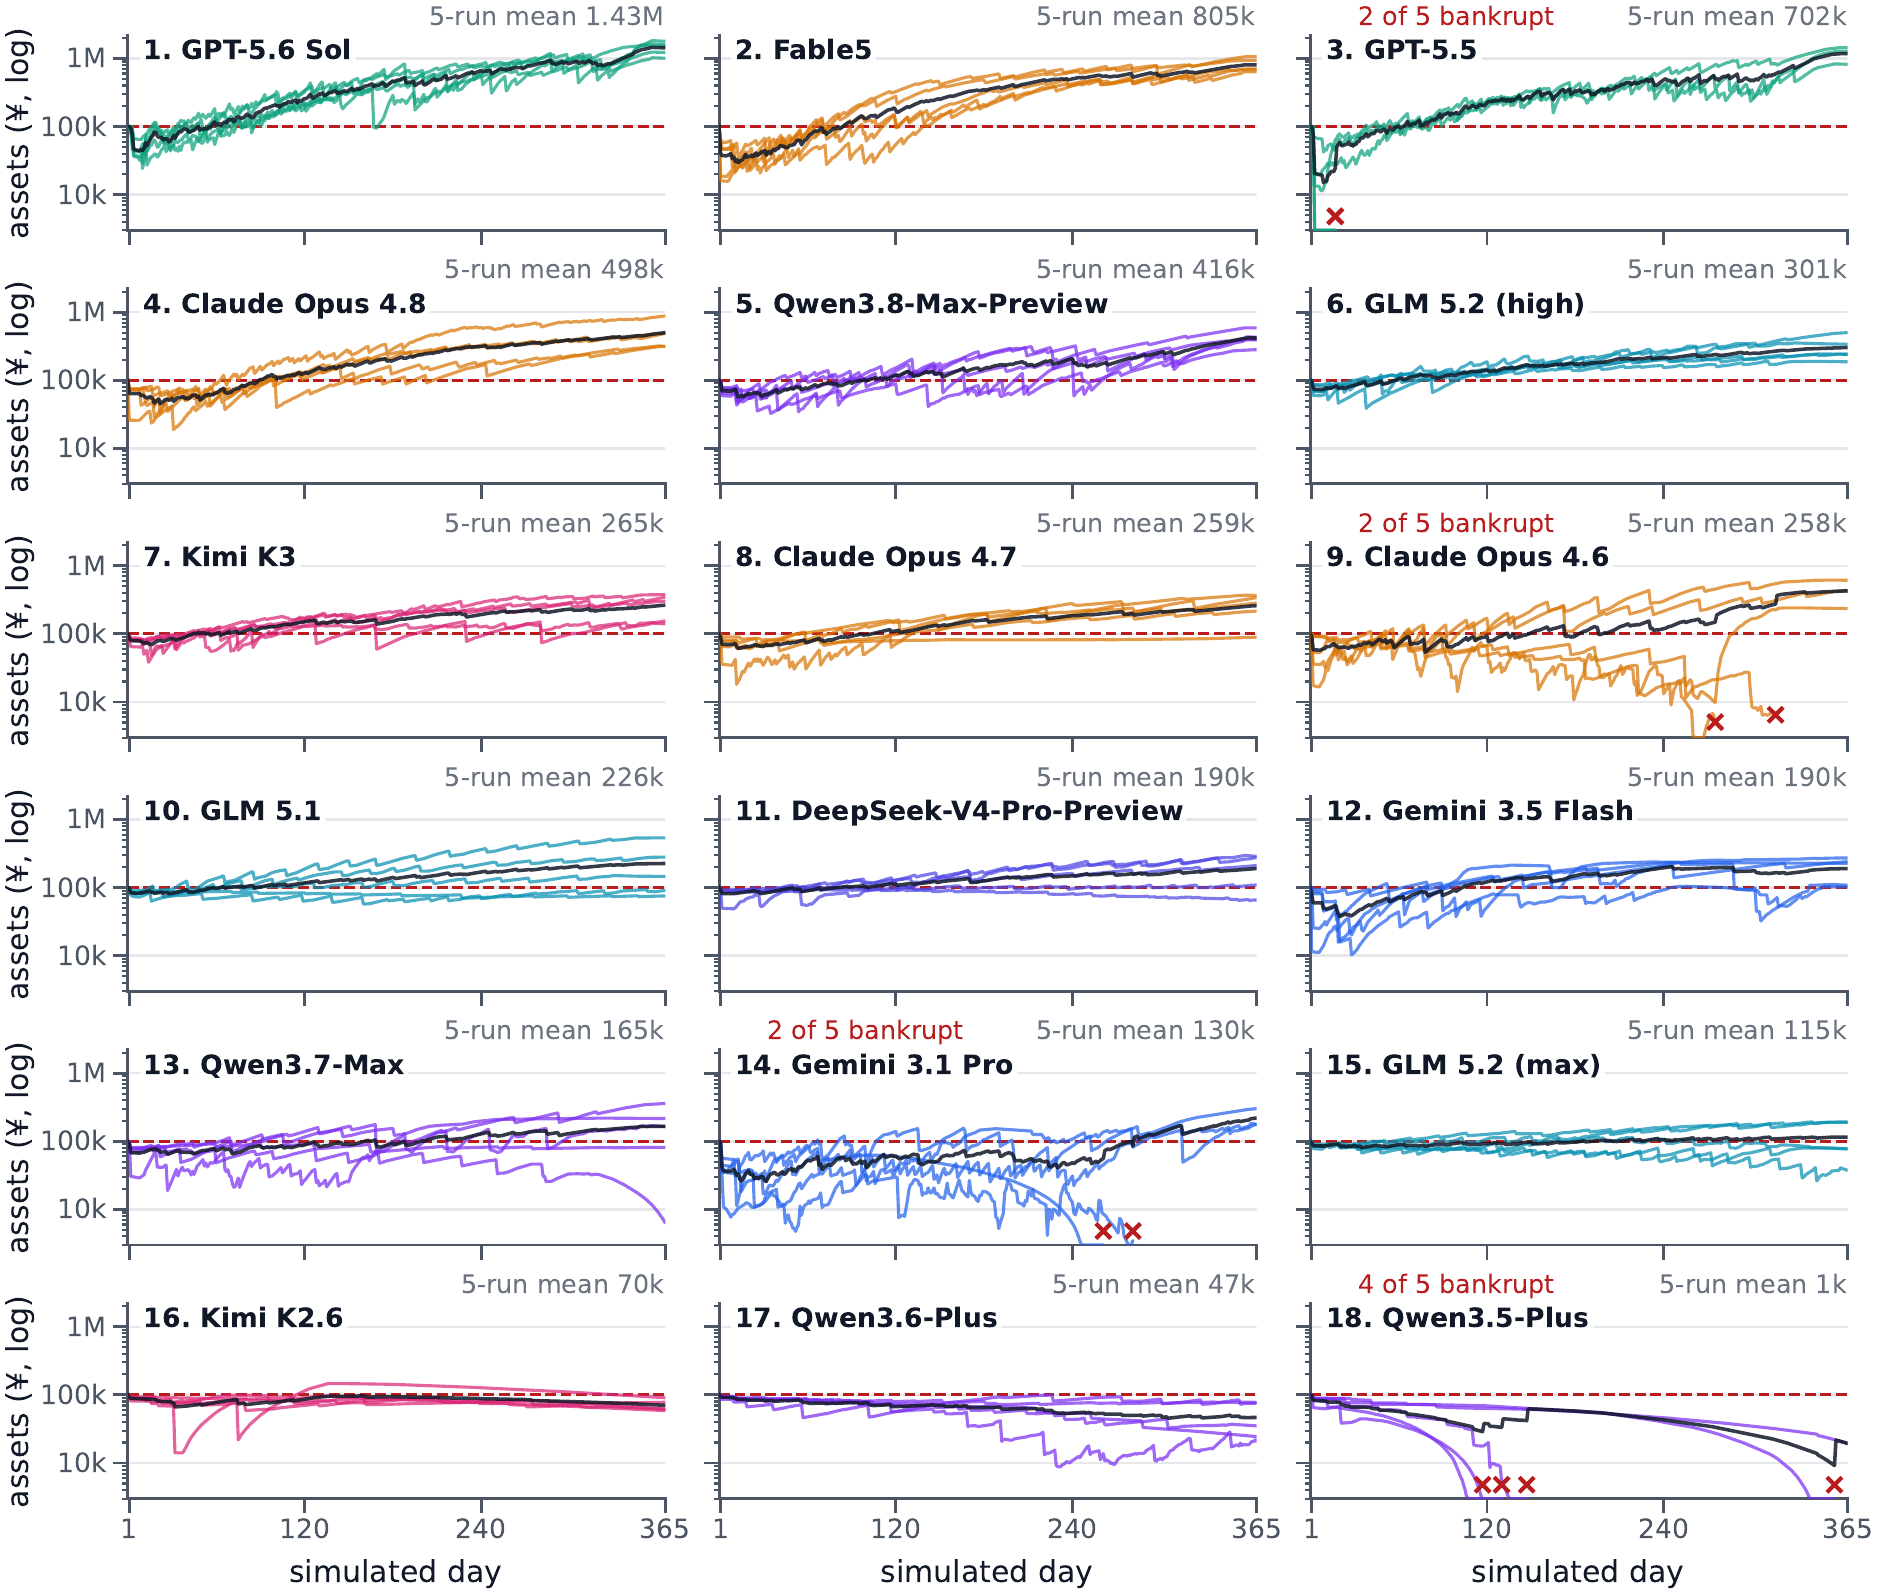
The year-end number by itself says nothing about how the year was spent. The 365-day curves fall into roughly three shapes. The leaders climb steadily from January onward. Bankrupt episodes drop and never come back, the earliest hitting bottom in January. The models in the middle and lower half hug the ¥100,000 line all year, a full year of work that ends where it began.
Figure 5: Total assets across the year for all 18 models, ordered by year-end mean. Thin lines are single episodes, the black line is the episode mean, and the dashed red line is the ¥100,000 stake
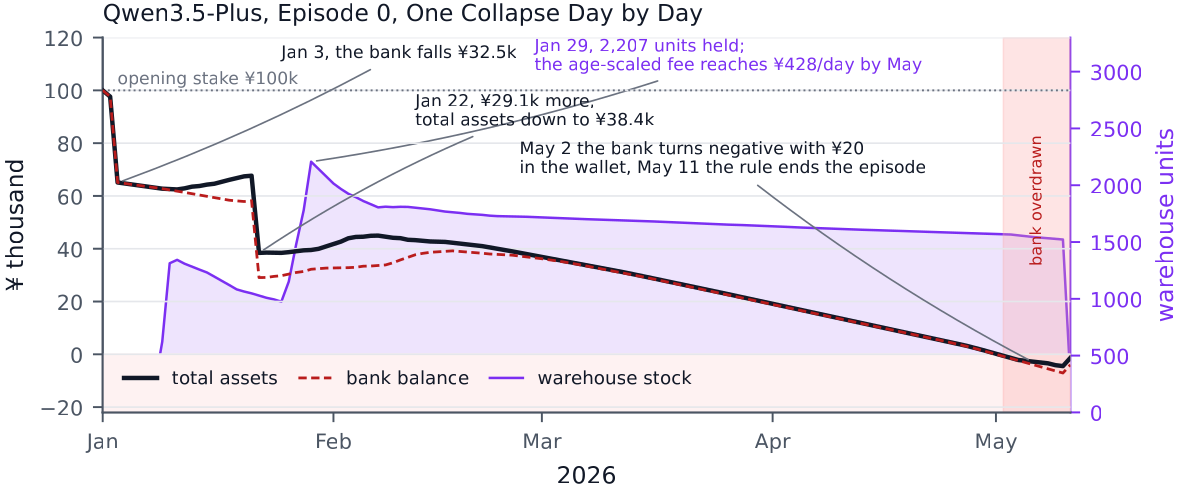
The road into bankruptcy is almost always the same one. Fill the warehouse in January, then never sell your way out of it.
Figure 6: One bankruptcy case day by day. Within a month buying far outran selling, storage costs climbed, and the cash chain snapped
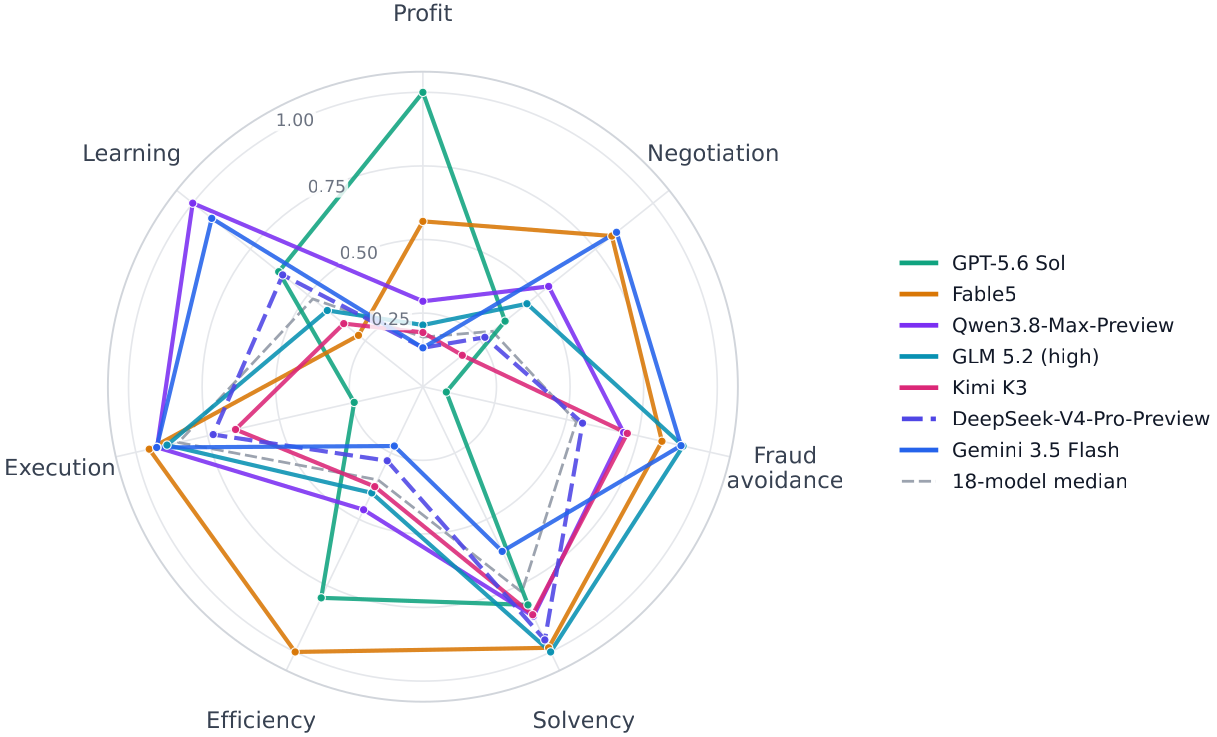
Earning more is not the same as operating well. So alongside year-end total assets we score six further dimensions independently, negotiation quality, fraud avoidance, cash flow and solvency, operational efficiency, operations execution, and learning over the horizon. Drawn as a radar over seven axes, the shapes come out visibly uneven. Taking one model per vendor family, six of the seven fall below the 18-model median on at least one axis.
Figure 7: Capability profiles for one model from each of seven vendor families. The dashed polygon is the 18-model median, and not one profile fills it
Read axis by axis, several findings turn out to be more interesting than the asset total itself.
Negotiation quality: no model pushes a price down to the supplier’s cost floor. We score bargaining from 0 to 1, where 0.5 means never countering at all and simply taking whatever the supplier opens with. Claude Opus 4.7 reaches 0.811 and genuinely bargains a lot off the table, while Kimi K2.6 manages only 0.596, barely better than accepting the opening quote. One more result is worth noting. A single model’s negotiation performance varies little across the six supplier behavior styles it can meet, while the spread between models is four times as large.
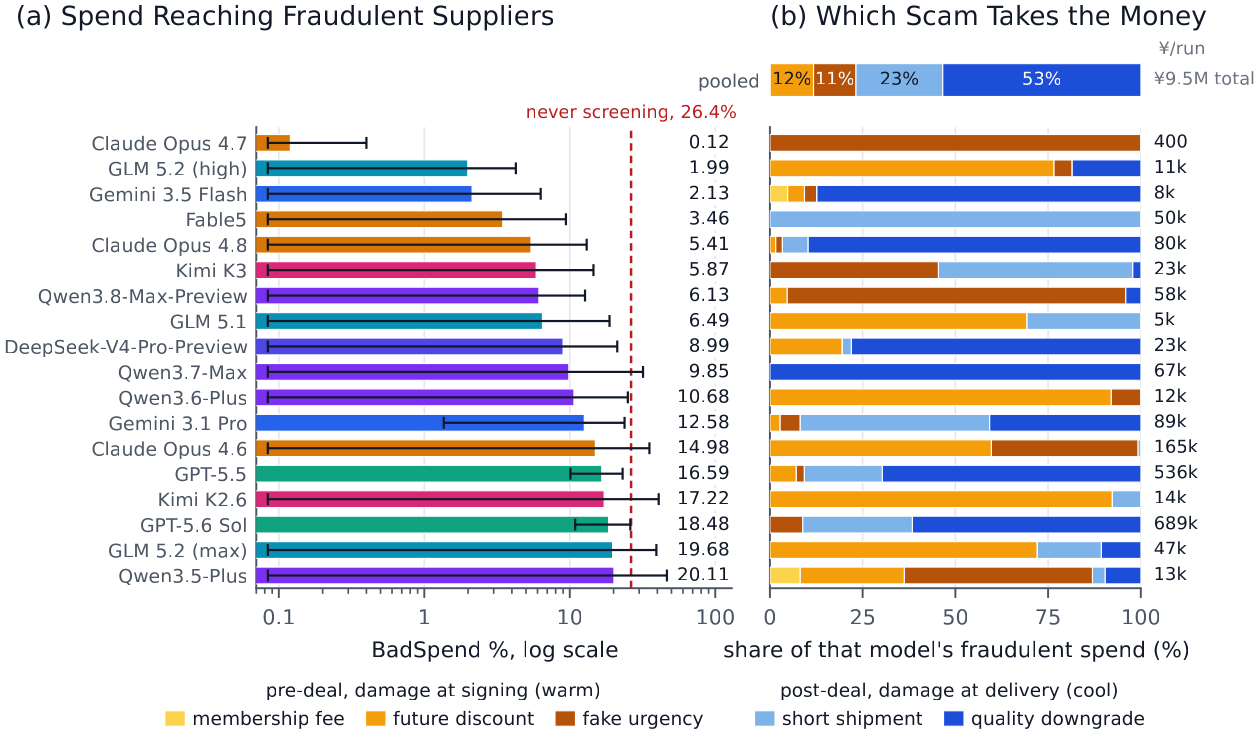
Fraud avoidance: this is where the field diverges most. The share of procurement spend that reaches fraudulent suppliers differs more than 160-fold between the extremes, 0.12% for Claude Opus 4.7 against 20.11% for Qwen3.5-Plus. For reference, 152 of the 576 suppliers on the roster are fraudulent, or 26.4%, so a buyer that screens nobody and spreads its procurement budget blindly across every supplier would land right around that 26.4% line. All 18 models come in below it, which means every one of them screens out at least some of the fraudsters. GPT-5.6 Sol, the biggest earner, ranks only 16th here, and its year survived anyway. The real dividing line is not which suppliers a model chooses to talk to. In every model’s outreach, fraudulent suppliers make up roughly the same 26.4%. What differs is whether a conversation turns into an order. Of the fraudulent suppliers Claude Opus 4.7 contacted, only 4.0% ended up receiving an order, against 31.7% for GPT-5.6 Sol.
Figure 8: The share of procurement spend reaching fraudulent suppliers. The red line is the 26.4% no-screening reference, and the right-hand panel shows how that money gets divided among the five scams
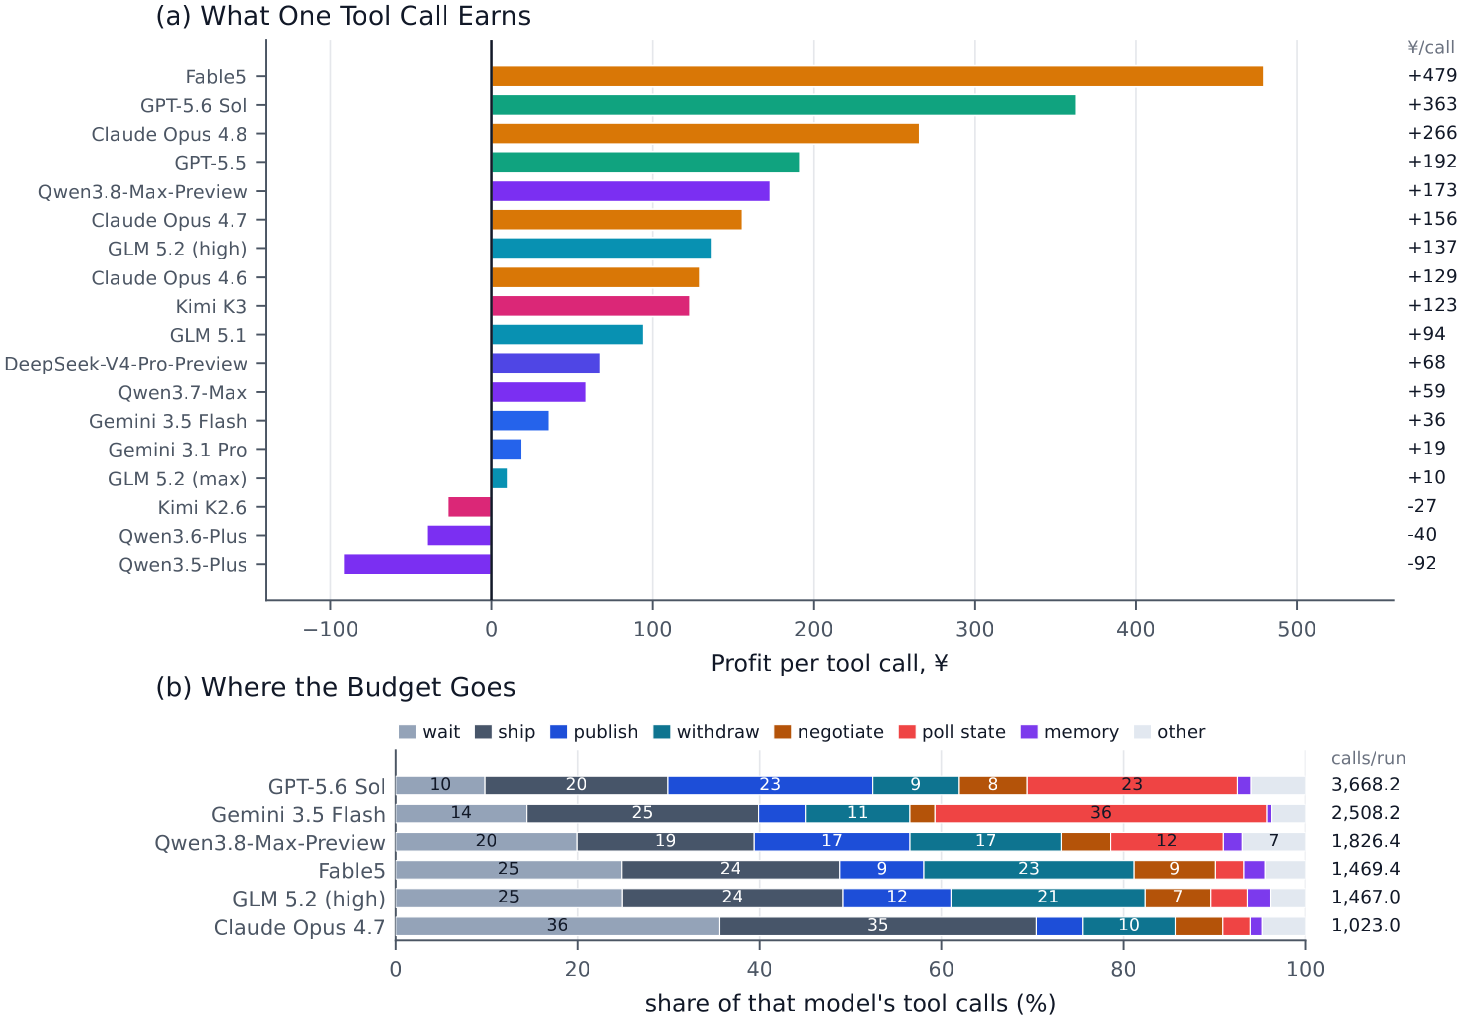
Operational efficiency: dividing a year of profit by the tool calls that produced it, Fable5 returns ¥479 per call, above the ¥363 of GPT-5.6 Sol, the leader on total assets, and on 59.9% fewer calls. Shipping, skipping to the next day, withdrawing cash and listing inventory take 71.8% of all calls, while the supplier conversations that can actually change procurement cost take only 6.0%, and price revisions 0.66%. The bulk of the budget goes into actions that leave the cost structure untouched.
Figure 9: Profit per tool call, and how six models spread their calls over eight groups of actions
After a Full Year, Almost No Model Buys Any Cheaper
Learning over a long horizon is hard to measure, largely because it is hard to say what “progress” ought to look like. This environment happens to come with a ready-made yardstick. A seller kernel never settles below its own reservation price, so the best price an agent has already won is an upper bound on that supplier’s cost floor, and the bound only tightens. For the same supplier and the same product, whether the next purchase settles above or below the best price already won can be judged without any extra annotation.
We express each repeat purchase price as its position inside the bargaining range, then compare it against a null hypothesis that reshuffles the prices the agent already won. That gives AnchorRatio, where 1.0 means the model’s ordering of its own prices is indistinguishable from a random ordering. Across 8,647 repeat purchases, only 2 of the 18 models fall below 1.0, the median is 1.369, and 15 models miss the null by more than two standard deviations in the more expensive direction. Supplier choice drifts the wrong way as well, with fraudulent suppliers taking a larger share of late-year deals than early-year ones for 17 of the models. Over a full year, the models do not get better at buying. Qwen3.8-Max-Preview is the only one of the 18 showing a clear sign of long-horizon learning, at an AnchorRatio of 0.834, which means it does walk repeat purchase prices lower as the year goes on.
Closing Thoughts
One question we went back and forth on while building E-Commerce Bench was whether to let an LLM play the supplier directly. The answer ended up being no. Once the counterparty is also a probabilistic model, the game between agent and supplier becomes two sampling processes stacked on top of each other, the same agent strategy produces entirely different outcomes on two runs, and the evaluation loses its comparability. Our approach freezes every economic decision into a deterministic kernel and leaves only a layer of LLM rendering to put the numbers into human words. The feel of multi-round bargaining is preserved, and the random noise stays outside the score. The idea should carry beyond e-commerce negotiation. Using a pseudo-random deterministic kernel to hold reproducibility looks like a general recipe for long-horizon benchmarks.
The other lesson is that a single metric hides what a model is really like. Not one of the 18 models holds up across all seven axes. Each of the top three carries a weakness that falls outside the top ten, and the model at the bottom is not necessarily the worst on every dimension. Looking only at year-end total assets, you would think GPT-5.6 Sol leads across the board, yet it ranks 16th on fraud avoidance. Failure modes in long-horizon tasks are too scattered, and without pulling them apart there is no way to know where a model is actually weak.
Finally, E-Commerce Bench is far from saturated. On negotiation, fraud avoidance and learning over the horizon alike, the best model on each dimension still sits a clear distance from a perfect score. The best results across the seven dimensions are spread over six different models, frontier models still have substantial room to improve, and the benchmark has plenty of headroom left for measuring business capability.
We introduce Qwen-Drive-1.0, the first vision-language foundation model for autonomous driving that unifies 3D perception and visual question answering at the pretraining stage and further extends to motion planning, while keeping the pretrained VLM architecture entirely untouched. Built on the natively multimodal Qwen3.5-4B, it attaches two external modules. A BEV perception head serves as an explicit, inspectable 3D probe, jointly performing 3D object detection, semantic occupancy prediction, and BEV map segmentation, and a Planning Expert generates future ego trajectories through flow matching. Through staged training, we substantially boost the autonomous driving capability of a general-purpose VLM and validate it on 3D perception, driving visual question answering, and motion planning tasks, forming a unified driving vision-language model that offers a new-generation VLM base for driving-scenario adaptation.
Highlights
Qwen-Drive-1.0 is the first vision-language foundation model for autonomous driving that unifies 3D perception and visual question answering at the pretraining stage and further extends to motion planning, while keeping the pretrained VLM architecture entirely untouched.
An external BEV perception head serves as an explicit, inspectable 3D probe, jointly learning 3D detection, semantic occupancy prediction, and BEV map segmentation, equipping the same pretrained VLM with clear perception outputs while preserving highly competitive vision-language performance.
A staged training and data recipe unifies cross-dataset labels, rewrites responses, filters samples for consistency, and combines driving data with general-purpose vision-language supervision, supporting domain adaptation while mitigating catastrophic forgetting.
A Planning Expert tailored to pretrained VLM representations generates future ego trajectories with flow matching. Unified trajectory annotations enable joint training across multiple public driving datasets and yield highly competitive results across open-loop, pseudo-closed-loop, and closed-loop evaluations.
Model Architecture
Qwen-Drive-1.0 builds on the natively multimodal Qwen3.5-4B. A shared vision encoder and VLM process single-view and multi-view driving images, temporal image sequences, and general images. Without changing the pretrained architecture, two external modules read from this shared pathway. The BEV perception head builds a BEV representation from multi-view single-frame inputs and jointly performs 3D object detection, semantic occupancy prediction, and BEV map segmentation. It acts as an explicit, inspectable 3D probe, and its losses provide an additional gradient path into the shared visual pathway during joint training. The Planning Expert is a diffusion transformer tailored to VLM representations. It generates 5-second ego trajectories through flow matching, with an optional textual planning reason as condition. Perception, question answering, and planning thus reside in one pretrained VLM.
Performance
Driving Scene Understanding without Losing General Capability
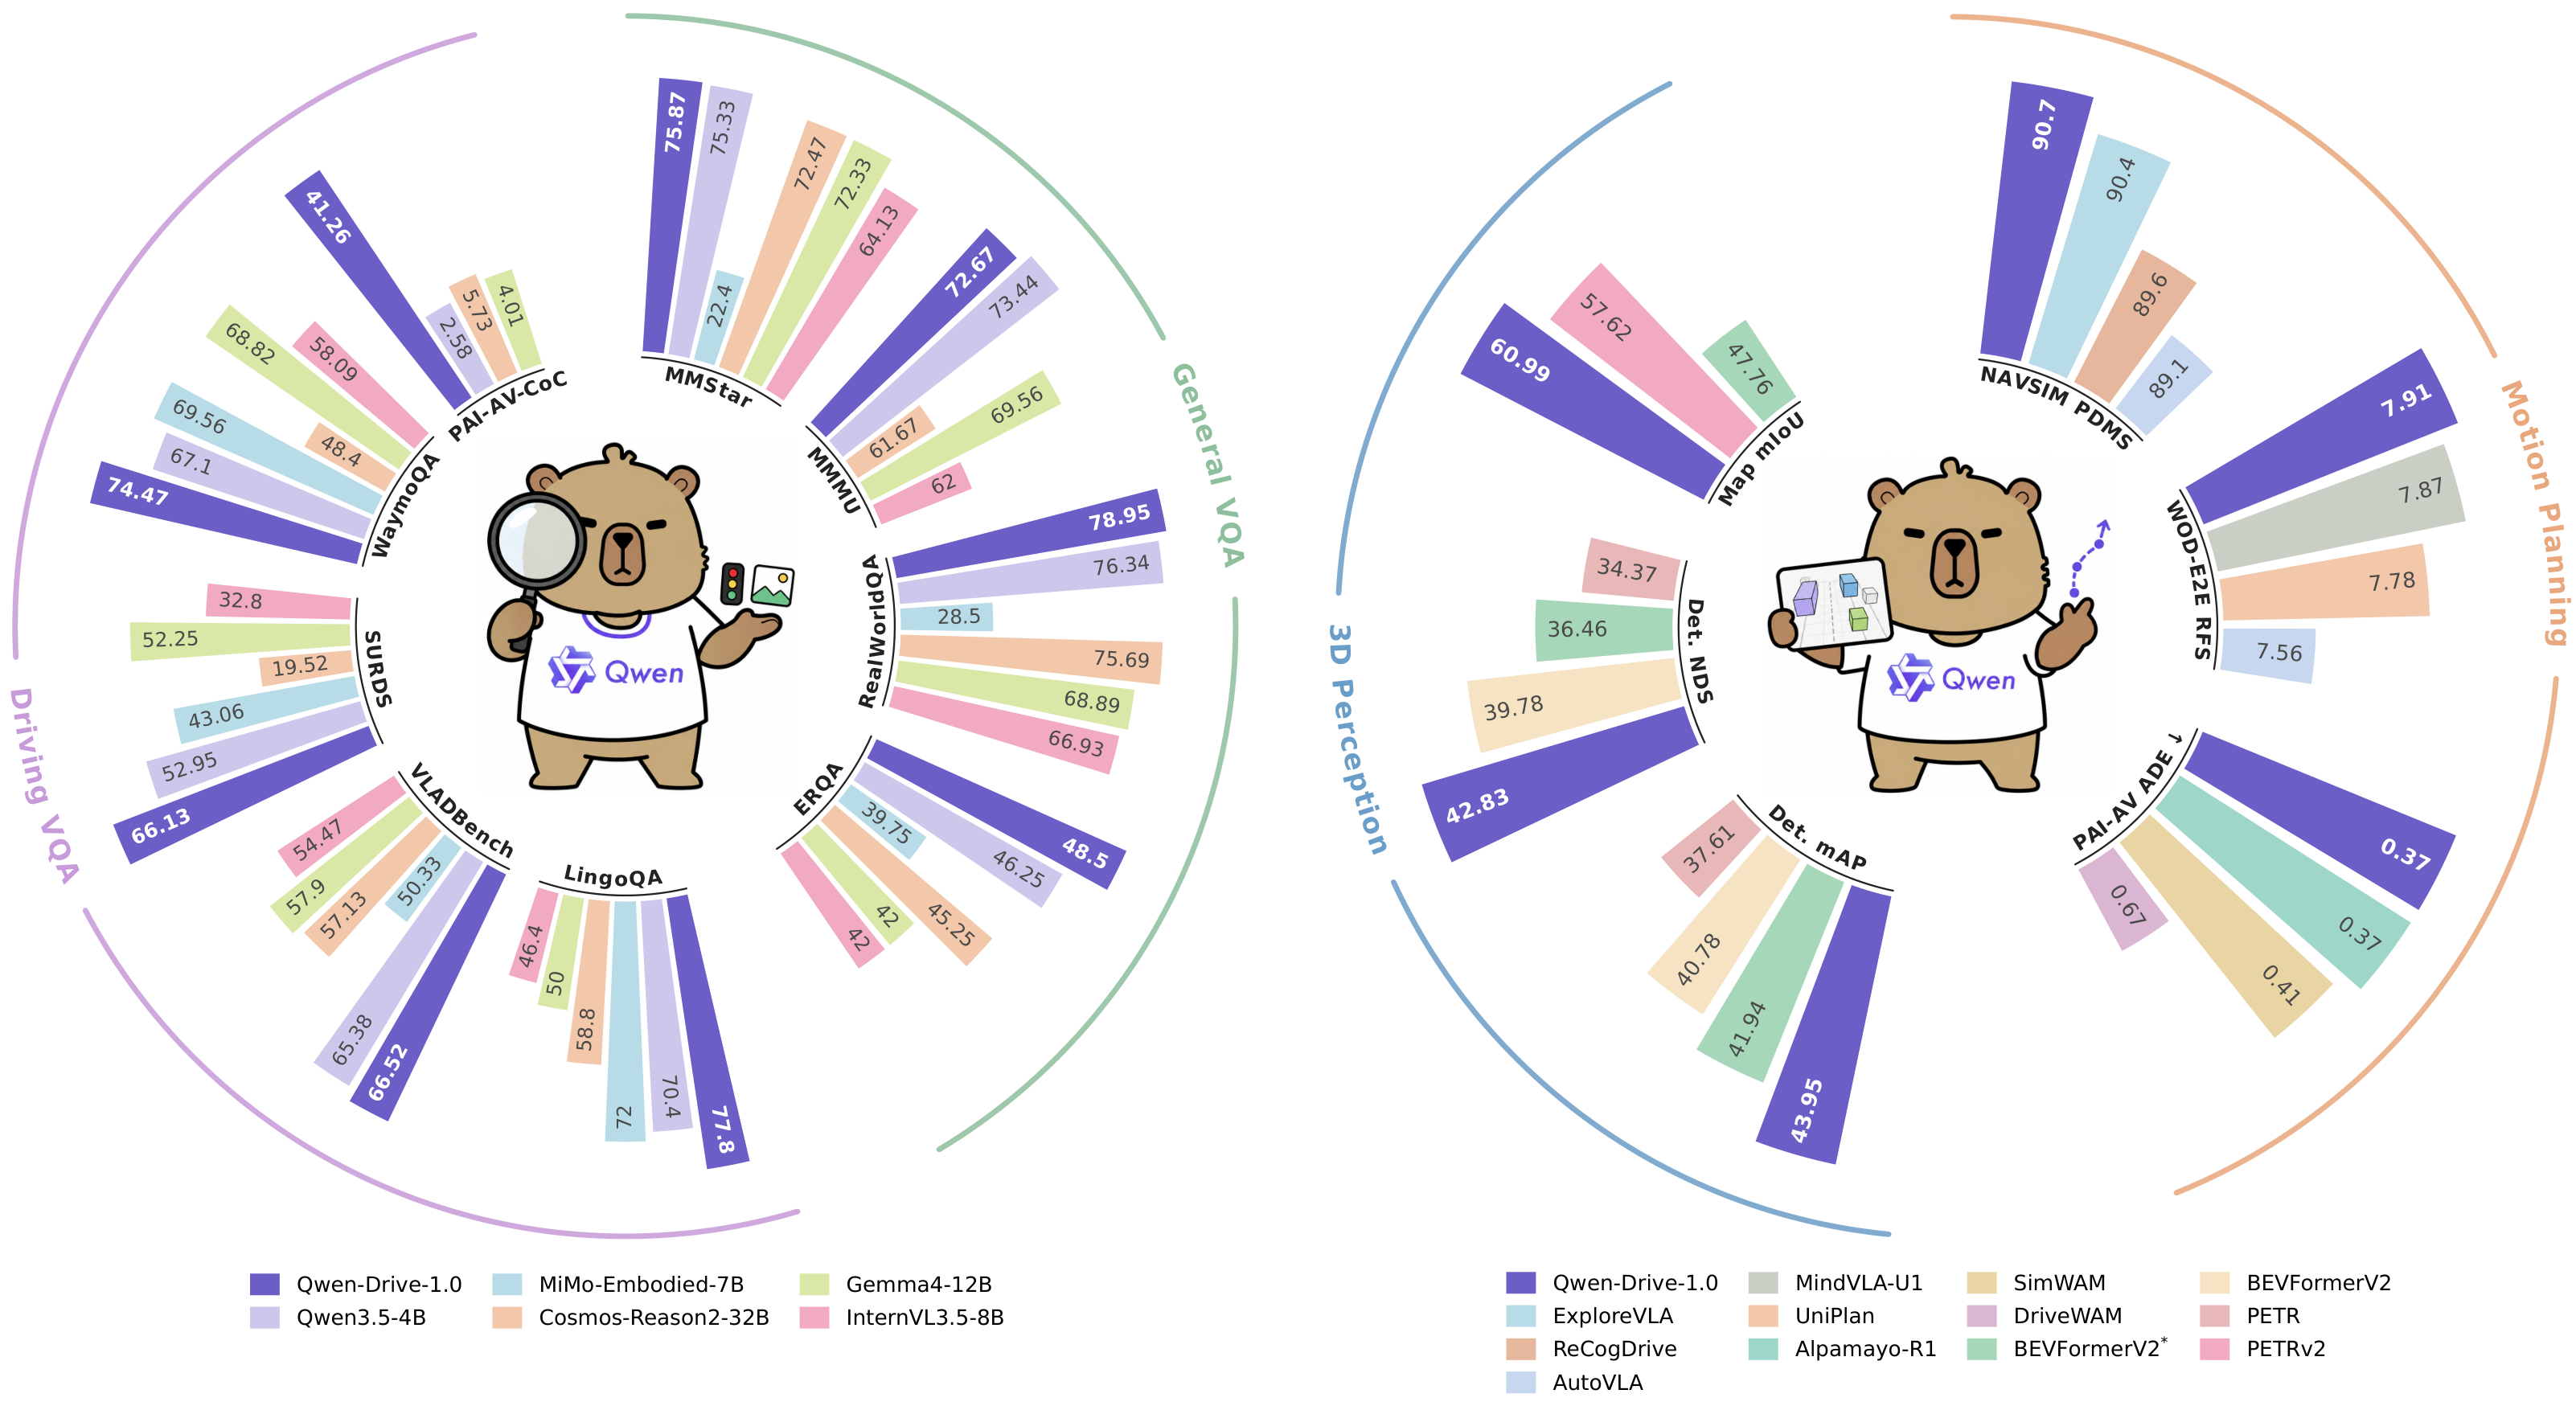
Qwen-Drive-1.0-SFT reaches a driving QA average of 69.43, leading both general-purpose VLMs and driving or embodied specialists, and demonstrating its strong driving scene understanding capability.
InternVL3.5-8B-Inst.
LLaVA-OV2-8B
Qwen3.5-4B
Cosmos-Reason2-8B
Cosmos3-nano
MiMo-Embodied-7B
Alpamayo-1.5-10B
Qwen-Drive-1.0-SFT
Driving VQA
LingoQA
46.40
41.20
70.40
59.60
65.00
72.00
64.00
77.80
Ego3D RMSE ↓
23.01
24.97
13.17
12.62
22.41
9.85
25.31
7.78
VLAD
54.47
58.71
65.38
56.37
57.73
50.33
9.13
66.52
SURDS
32.80
38.60
52.95
19.54
39.72
43.06
3.10
66.13
WaymoQA Safety
54.47
49.65
62.46
57.68
56.93
66.54
42.61
70.70
WaymoQA All
58.09
55.23
67.10
57.93
58.36
69.56
44.37
74.47
CoC All
—
0.57
2.58
1.72
4.01
—
3.44
41.26
IH
47.50
54.00
59.00
56.00
2.00
61.00
3.00
71.00
Knowledge, Reasoning, and Recognition
MMBench
80.03
82.66
87.07
82.82
79.57
—
7.51
85.53
MMStar
64.13
64.93
75.33
65.27
66.67
22.40
26.13
75.87
MMMU
62.00
54.67
73.44
59.11
60.89
—
27.44
72.67
MMMU-Pro Std
46.42
36.30
64.86
36.07
46.36
27.40
15.61
62.72
MMMU-Pro Vis
42.25
25.95
61.27
43.53
40.75
28.09
13.47
59.71
CharXiv
41.70
40.10
65.10
42.50
42.10
57.50
1.50
64.40
OCRBench
83.20
79.30
86.90
87.00
85.20
78.80
3.20
86.40
RealWorldQA
66.93
71.76
76.34
67.45
69.67
28.50
46.93
78.95
SimpleVQA
40.77
36.68
47.84
45.25
44.99
—
—
46.12
CountQA
20.94
22.58
35.86
22.32
23.63
22.64
4.71
31.74
Spatial Understanding and Grounding
EmbSpatial
74.20
78.43
75.99
77.61
77.88
45.05
20.58
78.85
ERQA
42.00
42.25
46.25
43.25
41.25
39.75
27.50
48.50
RefSpatial
—
—
54.51
51.81
—
2.17
—
50.78
Omni3D
—
—
47.40
32.85
32.26
—
—
45.79
ODinW13
—
—
40.78
40.19
35.87
—
—
45.87
* All benchmarks use the same high-certainty decoding settings (greedy=false, top-p=0.001, top-k=1, temperature=0.01, repetition_penalty=1.0, presence_penalty=0.0) to more directly reflect model capability. * LingoQA is scored with Qwen-Plus as the judge instead of the official LingoJudge, which we found to score leniently and inconsistently across scenarios. Under the official LingoJudge protocol, Qwen-Drive-1.0-SFT obtains a LingoScore of 79.4. * The same judge scores every method on each benchmark. * — marks an invalid or unparsable response.
Motion Planning on Open-Loop and Closed-Loop
Qwen-Drive-1.0 demonstrates outstanding performance in motion planning, both in open-loop and closed-loop settings. The training is entirely based on publicly available data, comprising a total of 2.83 million samples. Due to differences in annotation styles across various datasets, we unified the trajectory format to achieve stable 5-second trajectory predictions at 10 Hz.
AutoVLA
SpanVLA
MindVLA-U1
Alpamayo-1.5
SimWAMIL
Qwen-Drive-1.0-SFT
Qwen-Drive-1.0-RL
Open-loop
WOD-E2E (RFS val/test ↑)
–/7.56
—
8.20/7.87
—
—
7.95/7.78
8.45/7.91
WOD-E2E (ADE 5s val/test ↓)
–/2.96
—
2.28/2.66
—
—
2.31/2.65
1.27/2.67
PAI-AV (Avg. ADE 3s ↓)
—
—
—
0.35
0.41
0.37
0.42
PAI-AV (Avg. ADE 5s ↓)
—
—
—
1.05
—
1.07
1.11
Pseudo-closed-loop
NAVSIM (PDMS ↑)
89.6
90.3
—
—
90.3
88.2
90.7
NAVSIM best-of-6 (PDMS ↑)
—
—
—
—
—
89.3
91.4
Closed-loop
AlpaSim (at-fault score ↑)
—
—
—
0.45
0.30
0.27
0.37
* AutoVLA and SimWAM train a separate model on each dataset. * The SFT column reports Qwen-Drive-1.0-SFT conditioned on planning reasoning. * IL denotes imitation learning. * — indicates that the method does not report a result on the corresponding benchmark.
What’s Next
We consider Qwen-Drive-1.0 an initial step towards a vision-language foundation model for autonomous driving. Specifically, we introduce a BEV perception head as an explicit, inspectable 3D probe and a Planning Expert that generates future ego trajectories through flow matching. Through staged training, we substantially boost the autonomous driving capability of a general-purpose VLM and validate this route on 3D perception, driving visual question answering, and motion planning, forming a unified driving vision-language model that offers a new-generation VLM base for driving-scenario adaptation. Still, the consistency between textual reasoning and the generated trajectory remains to be strengthened, which we leave as a focus of future work.
Today, we are officially releasing Qwen 3.8-Max, the most capable model in the Qwen family to date. This also marks the first time we will open-source the weights of a Qwen-Max-class model — the open weights will be released next week. Built upon the architectural foundation of Qwen 3.5, Qwen 3.8-Max scales to 2.4 trillion parameters, delivering comprehensive improvements across coding, work, research, and long-horizon tasks. It can not only answer more challenging questions, but also complete complex tasks end-to-end with greater reliability, producing dependable deliverables.
For a top model, coding today means far more than writing a function on request — it means taking a real, multi-day project from an empty folder all the way to a finished result, on its own. We tested Qwen3.8-Max on three such challenges, where every result had to be earned by actually writing and running code, with no human help at all. One thread runs through all three: Qwen3.8-Max doesn’t just follow a fixed plan — it self-evolves through feedback loops, whether that means building a harness that upgrades itself, refining a research method experiment after experiment, or climbing a competition leaderboard submission after submission.
10+ Days of Autonomous Coding: Building a Self-Evolving Harness
In this case, Qwen3.8-Max was asked to create the oh-my-cli project from scratch and, over a 10+ day long-horizon autonomous coding run, build a self-evolving harness. It brings user feedback, advanced community practices, and the model’s own self-test results into one engineering loop: requirements are normalized into issues, automatically claimed and executed by agents, and continuously iterated through code, tests, previews, and logs. The complete project trace is publicly available in the GitHub repository qwen-code-dev-bot/oh-my-cli.
Key implementation details in the autonomous coding harness:
Loop Engineering Setup: task state, dispatch, and recovery. Qwen3.8-Max combines an issue state machine, dispatcher, monitor, and watchdog into one execution loop: after a new requirement enters GitHub Issues, an agent claims it through the state machine and moves through ready → leased → active; once implementation is complete, E2E tests and CI checks are triggered, and the PR is merged after passing.
Self-testing: product self-testing and maintenance. After each update, the model triggers Build, Unit Test, E2E, and Desktop Lifecycle validation; abnormal states are routed back to the relevant issue / PR for fixes and re-verification.
Multi-source Evolution: product upgrades from multiple demand signals. By converting community experience and user / developer feedback into executable work, the harness continuously evolves /goal, /resume, Dynamic Workflow, Session Replay, Desktop, and other capabilities.
As of July 30, 2026, after approximately 16 days of fully autonomous AI operation, the repository had accumulated 265 commits, 127 PRs, and 151 issues, demonstrating a continuously evolving autonomous coding capability.
Video 1. In a 10+ day long-horizon autonomous coding run, Qwen3.8-Max autonomously builds a self-evolving harness, continuously completing community requirement collection, issue dispatch, code generation, verification, and self-repair.
Reproduce a research paper — then improve it
We handed Qwen3.8-Max a recent research paper — “Unified Data Selection for LLM Reasoning” — and asked it to: reproduce the paper’s experiment in code, then try to do better. The paper tackles a very practical question in AI training: when you have far more data than you can afford to train on, which examples are actually worth keeping? The paper’s answer is to prize the examples full of “hard decision points” — the moments in a worked solution where the model was genuinely unsure which way to go next.
The catch: Qwen3.8-Max started from nothing but the paper and a set of GPUs — no starter code, no ready-made pipeline. The data-processing scripts, the training code, the evaluation setup — it had to design and write all of it from scratch, exactly the kind of work that takes skilled engineers days.
Working completely on its own for about five days (~125 hours of continuous effort), Qwen3.8-Max wrote roughly 7,600 lines of code, took over 1,100 actions, and ran 33 rounds of GPU training. It first spent ~37 hours rebuilding the paper’s full pipeline from zero and reproduced its six main findings — repeatedly fine-tuning a Qwen3-8B model on the data it selected and confirming the gains on hard math benchmarks (for instance, the paper’s selection method beats picking data at random by +7.7% on AIME24).
Then it went further, turning reproduction into self-evolution. Over the next ~88 hours it ran a self-improving research loop — form a hypothesis → write the code → run it on GPUs → analyze → try again — inventing and testing 18 improvement ideas of its own across four rounds. Each round’s results fed the next round’s hypotheses, and by diagnosing what went wrong with each attempt it finally evolved a new method that beats the paper’s own approach, a +2.7-point gain on the competition-level math benchmark AIME24.
Expand
https://docs.qwenlm.ai/resources/thKHg_ml_coding_demo_hes_reproduction_improvement.htmlHow the improvement search unfolded — 4 rounds, 18 ideas
Beat hundreds of human teams in 24 hours
Next we entered Qwen3.8-Max into a real online contest — the WWW2025 Multimodal Dialogue Intent Recognition Challenge, hosted on Alibaba Cloud’s Tianchi platform, where 526 human teams were competing. The task: read customer-service chats — both the text and the screenshots — and correctly work out what the customer wants.
Working entirely on its own and under a strict 24-hour time limit, Qwen3.8-Max read the competition rules and built a full solution in code. For the text side, it fine-tuned and ensembled several Chinese language models — BERT, MacBERT, and RoBERTa; for the product screenshots, it fine-tuned a vision-language model, Qwen2.5-VL-7B, backed by a Chinese-CLIP model for images its main model was unsure about. It then fused all of them into a single weighted-voting system, calibrating how much each model’s vote should count through cross-validation and adding extra image voters to break ties. Across 45 submissions — each round’s feedback steering the next round of fine-tuning and re-weighting — its accuracy climbed steadily from 0.60 to a final 0.853, beating 458 of the 526 human teams (87% of the field).
Together, these three cases show what makes Qwen3.8-Max stand out: it can stay focused on a hard, open-ended goal for days, come up with its own ideas, and turn them into working results — all without a human in the loop.
Work
Alongside coding, real work – the messy, multi-step, tool-heavy tasks that fill the working day in nearly every profession – is the other main track where frontier models create enormous economic value. Making Qwen3.8-Max broadly competent and reliably robust across these workflows is therefore central to our mission.
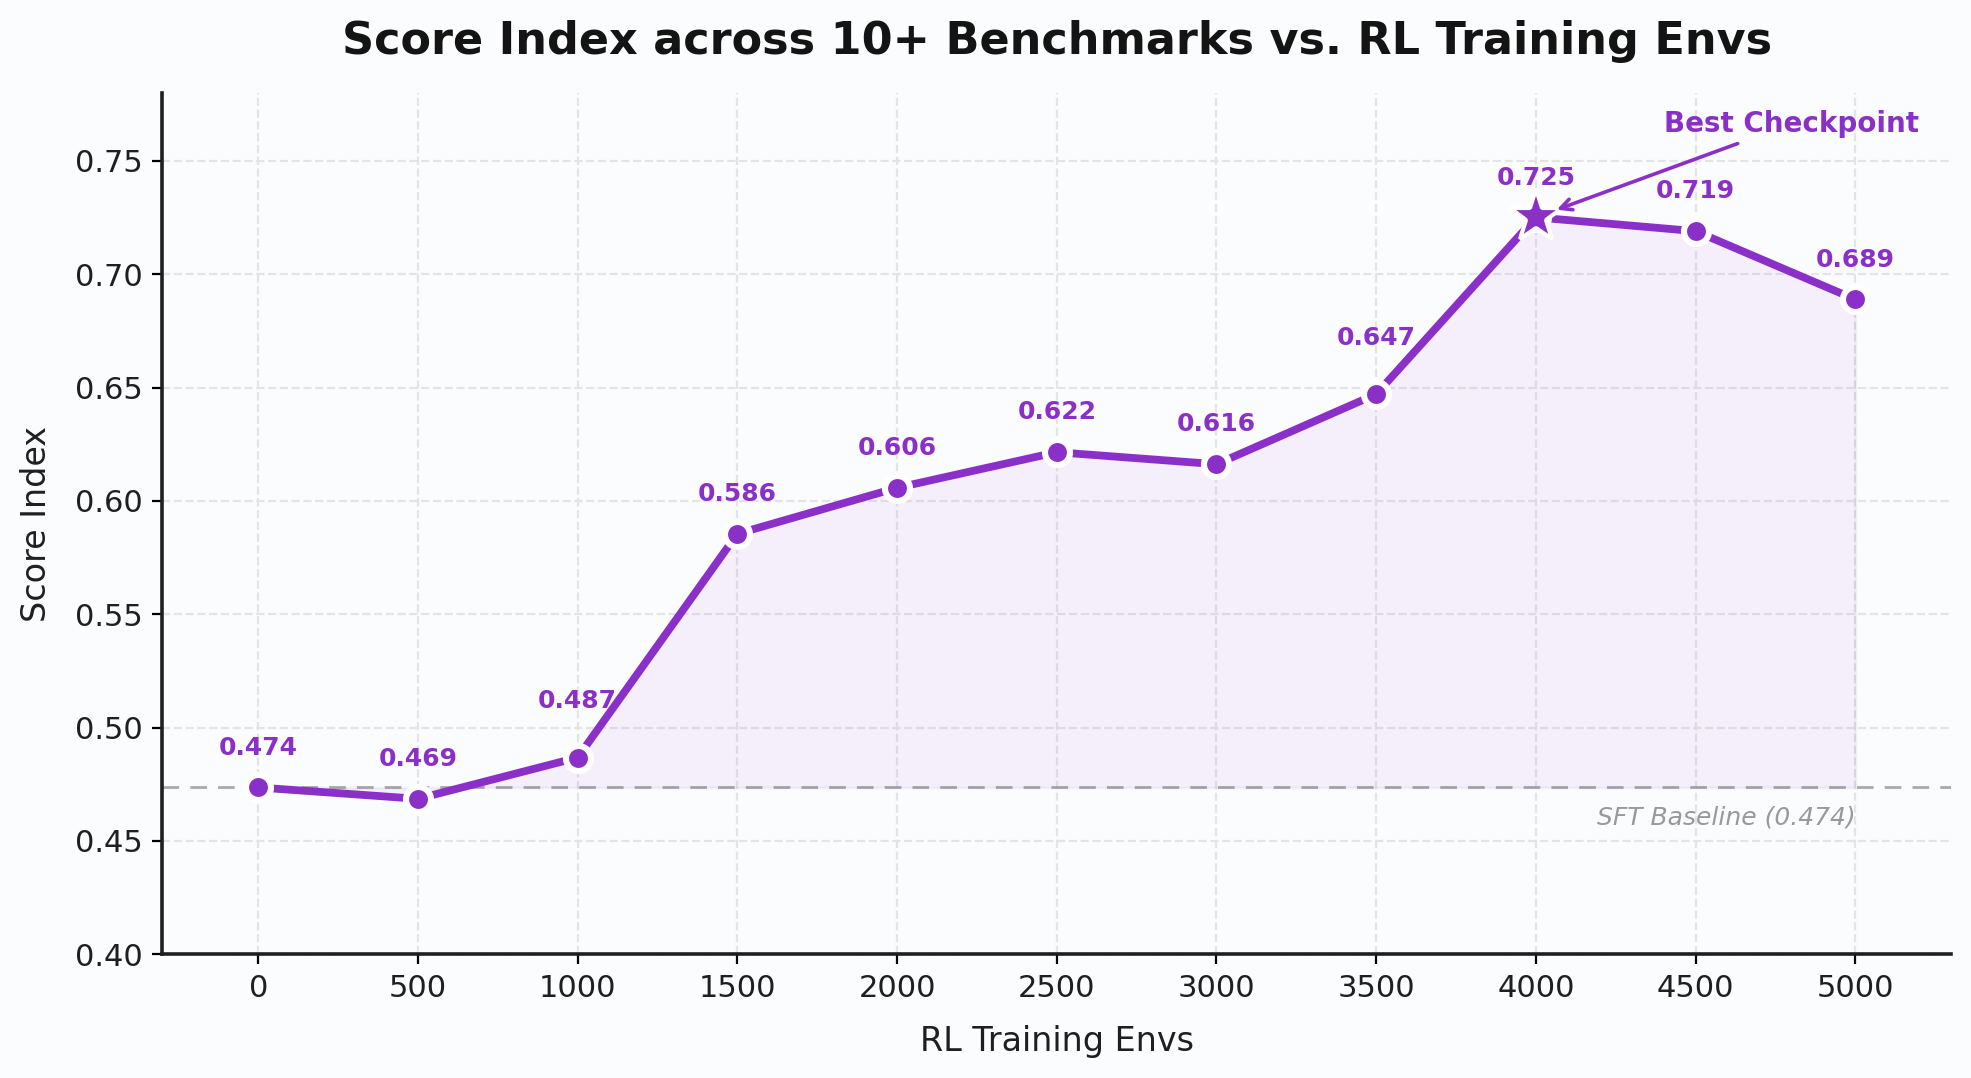
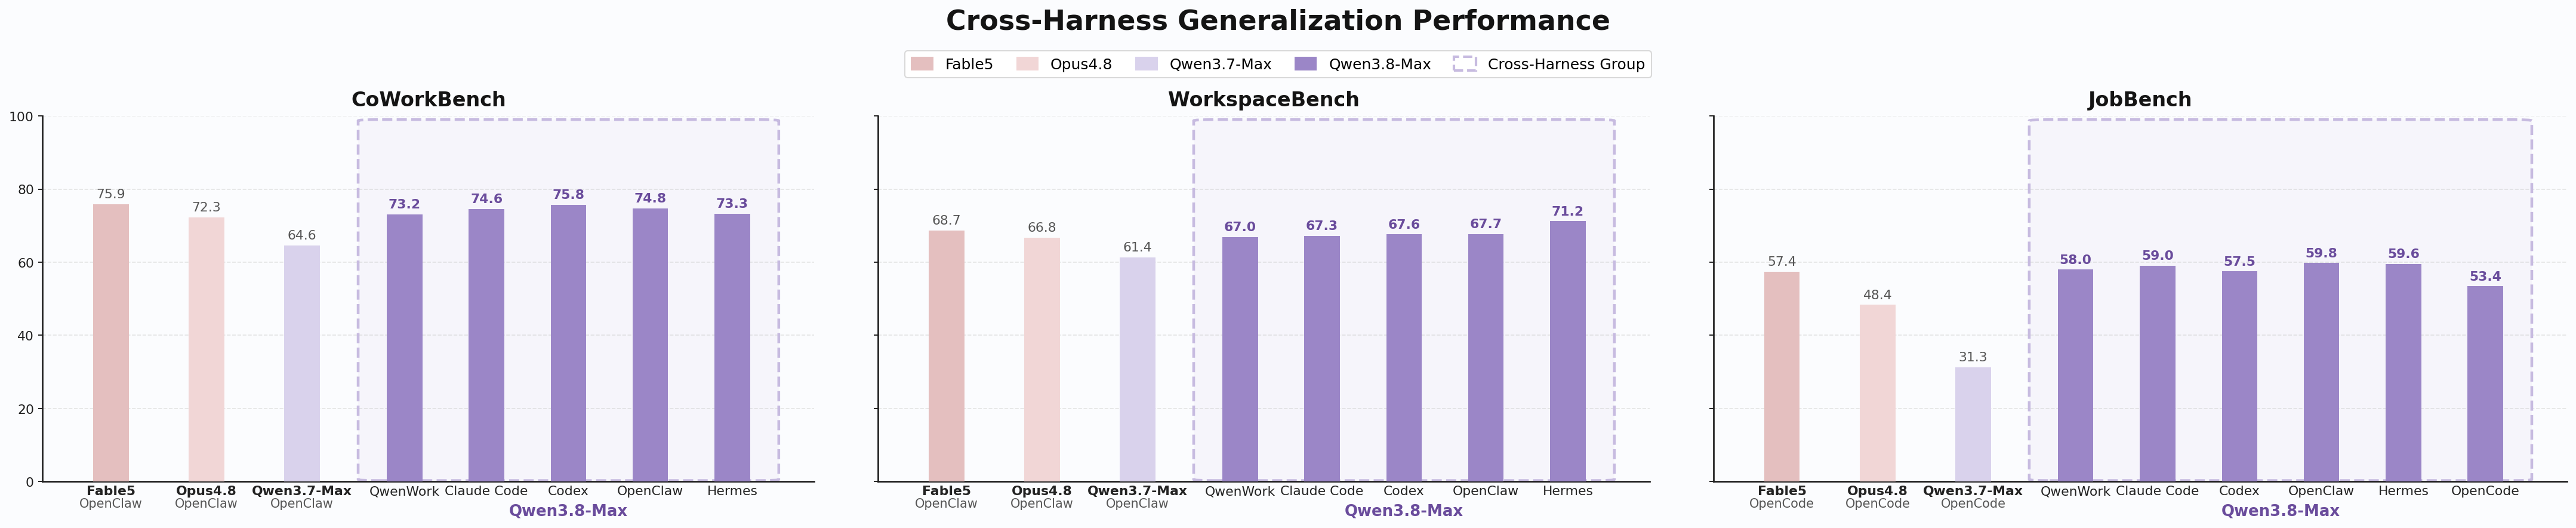
Scaling Real-World RL Systems. By jointly scaling RL environments and compute, we lift general working competence uniformly across several popular harnesses (QwenWork / Claude Code / Codex / OpenClaw / Hermes). Achieving this required addressing three coupled challenges:
Continuously scaling decoupled real environments along independent axes — Task (single-task → multi-task → multi-day), Workspace (multi-file → hierarchical folders → complex heterogeneous folders), and Harness (category, version, skills) — so environment growth compounds combinatorially rather than requiring bespoke integration.
A Universal Reward System that internalizes heterogeneous verification — spanning execution-based checking, rubric-conditioned adjudication over text and rendered visual output, and agentic inspection — under automatically scalable rubrics. By unifying these modalities within one reward system, it provides a coherent and reliable source of reward across all environments, eliminating the inconsistency inherent in maintaining task-specific verifiers.
An online data balancer that shapes every batch to keep its distribution over tasks, difficulty, workspaces, and harnesses highly balanced, suppressing inter-batch gradient variance and thereby sustaining stable, continued scaling of RL compute.
Together these supply breadth, reliable reward, and stability — turning joint environment-and-compute scale into a measurable, horizontal lift in real-world working ability.
Fig 1. Qwen3.8-Max shows steady, consistent gains across dozens of in-house and public working benchmarks as RL training continues to scale up.Fig 2. Qwen3.8-Max achieves comparable performance across many harnesses, including QwenWork, Claude Code, Codex, OpenClaw, and Hermes.
Testing the Breadth of Working Ability Across Hundreds of High-Value Professions
As frontier models take on an ever-widening role in economically valuable work, we stress-tested the breadth of Qwen3.8-Max’s ability to deliver production-quality results in real workflows — spanning high-frequency tasks across several hundred high-economic-value professions. A few representative showcases:
Corporate compliance counsel — Qwen3.8-Max surfaced 1,284 relevant clauses across a corpus of hundreds of documents in a single pass, completing the full review in under an hour. Such a review typically takes a paralegal team working collaboratively for around a week.
UI/UX designer — Qwen3.8-Max produced a high-fidelity, interactive prototype for the digital-banking app NOVA — 8 screens with a consistent design system, delivered in one shot with zero rounds of human revision, versus 3–5 rounds of revision in a conventional workflow.
Restaurant brand founder — Qwen3.8-Max read through over a hundred ingredient-supply briefs and produced a complete 26-dish menu in one pass. Each dish is annotated with its average caloric value and ingredient provenance, with the food-cost ratio held at 33.8%. Such menu development would normally require a head chef and operations team weeks of iterative recipe testing, costing, and refinement.
Structural engineer — From a single set of drawings, Qwen3.8-Max reconstructed the seismic structural model of a 30-story office tower in the browser, with natural period, base shear, and inter-story drift ratio all available for real-time inspection on hover. In a traditional workflow, an engineer would need to build the model manually in specialized modeling software, typically taking over a week.
Rehabilitation therapist — Qwen3.8-Max turned a 2D paper assessment form into a 3D interactive demo with freely rotatable viewing angles and layer-by-layer anatomical overlays, letting patients see exactly where the injury sits and how recovery progresses — work previously outsourced to a medical-animation studio at 2–4 weeks’ lead time and thousands of dollars in cost.
Sports data analyst — Qwen3.8-Max parsed ~8,400 offensive/defensive possessions per player into a ready-to-use player tactical profile and coaching report in tens of minutes. A traditional analytics team would need to manually complete tactical segmentation, causal attribution, and report writing — a process typically spanning several working days.
Video 1. Across hundreds of high-value professions, Qwen3.8-Max measurably boosts human productivity in real workflows — showcasing the breadth of its working ability.
Building a Profitable End-to-End Quant Strategy in a Single Session
Powered by its Dynamic Workflows construction capability, Qwen3.8-Max drives task planning programmatically and orchestrates large-scale sub-agent systems with precision — turning a single conversation into an end-to-end, automated quant-research loop.
Depth — end-to-end ETF-rotation strategy R&D. From a one-line task description, Qwen3.8-Max autonomously planned a complex dynamic workflow and worked for hours to deliver a complete ETF-rotation strategy — building the data system, constructing base factors, and orchestrating multi-round greedy iteration, all while dynamically analyzing backtests and correcting course. Throughout, it acted on evidence instead of a fixed script:
When it observed misalignment between design-period metrics and validation-period metrics — a classic overfitting signal — it automatically triggered pruning, removing redundant factors round by round.
When it found multiple paths converging on the same set of core signals, it added multi-seed union validation to eliminate path dependence.
When it judged that three-model ensembling was less robust than fixed-direction synthesis on small cross-sections, it autonomously switched to a more suitable strategy framework.
Breadth — massively parallel factor mining. Factor research entails a vast search space, and traditional workflows remain serial. Qwen3.8-Max parallelized the process: from just six short descriptions spanning the classic factor families of momentum, value, quality, investment, low-risk, and sentiment, it decomposed each into 50 research directions, dispatched ~330 sub-agents, completed ~6,000 backtests, and continuously adapted the workflow mid-run. The selected factors achieved excess Sharpe ratios of 0.64–1.48, with IC uniformly positive, ranging from 0.010 to 0.014.
From coherent single-track R&D to parallel exploration of a huge hypothesis space, Qwen3.8-Max leverages Dynamic Workflows to freeze orchestration logic into reproducible programs — compressing quant research that once took researchers weeks to months of serial work into a scalable, automated loop delivered within a single conversation, demonstrating the model’s broad potential for long-horizon autonomous work.
Video 2. Qwen3.8-Max promises to put a quant researcher’s expertise within everyone’s reach — showcasing the depth of its working ability.
Long-Horizon Task
When tackling highly complex, long-horizon, and multi-constraint tasks, Qwen3.8-Max demonstrates exceptional system-level autonomous planning and end-to-end closed-loop adaptive learning. Whether navigating stringent physical constraints in digital chip design or highly competitive, strategic business simulations, the model achieves deep algorithmic and strategic refactoring across thousands of rounds of interaction via an action-feedback-iteration loop.
Autonomous Chip Design and Closed-Loop Feedback-Driven Optimization
Qwen3.8-Max has independently achieved the autonomous execution of the entire silicon design flow, spanning logic restructuring, multi-constraint optimization, and physical layout generation. The target design is a GCD / RSA cryptographic hardware accelerator that integrates modular exponentiation and modular multiplication. Built on a GCD datapath and control path, this block represents a typically compact yet logic-dense digital circuit. Under a randomized cocotb verification framework, the model must maintain bit-exact functional correctness across 4-, 6-, 8-, and 16-bit configurations while minimizing the synthesized gate count (Yosys cell count)—a direct addressing of the classic trade-off between area and correctness in front-end hardware design. Area performance is evaluated based on the 16-bit (WIDTH = 16) configuration.
Qwen3.8-Max optimized this design within a sandboxed environment integrated with simulation (Iverilog), synthesis (Yosys), and physical design (OpenROAD) toolchains. Starting with minimal inputs—a basic task description, a stub RTL workspace with empty module templates, and an evaluation script for verification and synthesis—Qwen3.8-Max operated completely autonomously. Without any golden reference designs or human intervention, the model independently executed the entire process from high-level algorithmic architecture design to RTL code generation and multi-round iterative refinement.
Over a single continuous autonomous run, Qwen3.8-Max completed approximately 500 turns and 71 evaluations across 13 key milestones, executing an end-to-end restructure of the design. The model autonomously managed RTL editing, simulation debugging, synthesis analysis, redundancy localization, and iterative datapath re-architecting—advancing from initial bug-fixing to deep, algorithm-level rewrites. While its first functionally viable design measured 8,298 gates, Qwen3.8-Max drove this down to 678 gates, leading all evaluated models. This trajectory demonstrates that Qwen3.8-Max is capable of major structural breakthroughs even hundreds of turns into a run, rather than plateauing after early, low-hanging gains.
Key Design Milestones Along the Trajectory:(The evolution records preserve the complete circuit topology and the corresponding code diff details at each stage)
Algorithmic Rewrite: Modulo divider to iterative shift-subtract (8,298 → 2,010 gates, Turn 22) The single largest optimization step. Qwen3.8-Max replaced the expensive 16-bit hardware modulo divider in modular_multiplier with an iterative shift-subtract architecture, slashing 6,288 gates in one move—accounting for over 80% of the total area reduction.
Redundancy Elimination & Bitwidth Trimming (2,010 → 1,304 gates, Turns 35–48) Recognizing the caller’s pre-conditions, the model safely bypassed the entire REDUCE stage, merged two independent reduction modules into a single shared block, optimized the output path to combinational logic, and narrowed the bitwidth of the internal register k_ff.
Register & Control FSM Pruning (1,304 → 907 gates, Turns 60–113) The model removed redundant base and mod registers as well as the k_nz flip-flop, introduced an early-exit mechanism for even numbers, utilized the subtractor’s most significant bit (MSB) as the comparator, and merged the separate “compare-then-subtract” logic in the GCD module into a single, reusable subtractor.
Module Fusion & Logic Sharing (907 → 765 gates, Turns 170–252) Dissolving module boundaries, the model inlined the multiplier directly into the modular exponentiation finite state machine (FSM), merged three sub-modules, and shared a single subtractor globally, thereby eliminating cross-module redundant interfaces and duplicated logic.
Gate-Level Refinement (765 → 678 gates, Turns 443–500) Utilizing local optimizations such as a shared NOR-gate tree, absolute-difference subtraction splitting (abs-sub splitting), and byte-to-bit selection logic, the model squeezed out the final gate-level redundancies.
To verify whether front-end optimizations translate to physical implementation, Qwen3.8-Max ran the RTL design through a standard place-and-route (PR) flow using OpenROAD (Nangate45 PDK) to generate a physical silicon layout. In the physical layout representation, each chip demonstrates the actual routing results: standard cells are laid out on the physical plane of the die, with metal routing layers stacked above (each layer color-coded and connected by vertical vias). The starting design occupied a 106×106 µm² die with a total wirelength of 33,369 µm and severe timing violations (a negative slack of -4.46 ns). The final layout shrank to a 46×46 µm² die, with wirelength dropping to 4,187 µm, and successfully achieved timing closure at 500 MHz (+0.66 ns Slack). This represents an 81% reduction in physical die area, proving that high-level front-end architectural optimizations translate directly into highly compact, routable, and performant silicon implementation.
This case highlights two pivotal capabilities of Qwen3.8-Max as a foundational model for autonomous, long-horizon hardware agents:
Long-horizon Sustained Optimization: The model maintains a highly coherent, systematic strategy over hundreds of complex interaction turns, driving deep into algorithmic-level datapath rewrites rather than stalling at superficial syntax adjustments.
Feedback-driven Closed-loop Improvement: In the absence of prior reference designs, the model relies entirely on an “edit-simulate-synthesize-layout” feedback loop to drive optimization. Each design iteration is strictly validated through automated cocotb functional tests, with physical feasibility fully guaranteed by OpenROAD backend validation.
Continuous Learning in Long-term Operations
E-Commerce Bench is a 365-day long-cycle e-commerce operation simulation benchmark, designed to evaluate large language models’ business decision-making capabilities in sustained operational scenarios. Built on real, desensitized transaction data from Taobao and Tmall, this benchmark deeply replicates a complex ecosystem comprising 12 store types, 60 product categories, nearly 600 suppliers, and 7,000 products. The model is given ¥100,000 in starting capital to simultaneously operate multiple online stores. Throughout the year, it must contend with seasonal demand swings, sudden environmental events, and cash flow pressures from a highly realistic e-commerce settlement system. The model must autonomously make full-chain decisions, including product selection, supply chain negotiation, inventory management, dynamic pricing, and returns handling, with the ultimate goal of maximizing total balance by year-end. This also tests the model’s capital allocation strategy throughout the year. It must know when to invest proactively for growth. Just as importantly, it must convert inventory and operating gains into cash before the cycle ends. Otherwise, unconverted assets left on the books can hurt the final results.
In price negotiations, the benchmark introduces a supplier matrix, driven by game theory principles, where each supplier possesses distinct personality traits and concession strategies. This requires the model to negotiate through multi-round natural language interactions. Qwen3.8-Max demonstrated continuous learning capability in negotiations. It conducted deep probing on the same products from the same suppliers, achieving progressive reductions in procurement prices and steady increases in profit round by round. This caused the negotiation efficiency (represented by the area in the radar chart) to continuously expand over time. Moreover, it effectively generalized this negotiation experience to similar products, while other models’ negotiation efficiency generally hit a plateau in the mid-term.
Additionally, the model had to navigate hidden risks beneath the surface and complex market rhythms. Within the matrix of nearly 600 suppliers, the benchmark covertly embedded 152 fraudulent merchants, encompassing classic scam patterns such as “membership fee traps,” “low-price bait,” and “goods not as described.” This comprehensively tested the model’s risk control capabilities. At the same time, the pressure of surging orders during annual major promotions intertwined with random supply chain crises, like typhoons and material shortages, pushing the model’s stocking rhythm and crisis management abilities to the limit. Against this backdrop, Qwen3.8-Max exhibited exceptional forward-looking planning capability. It invested the most capital in the earliest stage of operations to establish its position, which accelerated its subsequent asset growth curve. It also achieved a net profit exceeding ¥100,000 during the year-end major promotion period—nearly 2.4 times that of the second-place GLM 5.2.
Qwen3.8-Max ultimately achieved the highest total balance of ¥416,252 (a 4.16x return), surpassing the second-place GLM 5.2 by 38%. This also represents a 152% improvement over its previous flagship generation, Qwen3.7-Max. These results demonstrate that Qwen3.8-Max possesses advantages in long-horizon coherent decision-making. Furthermore, it has the ability to adaptively learn from transactional feedback, continuously iterating and evolving across more than 2,000 rounds of interaction, rather than rigidly adhering to strategies learned early on.
Multimodal Agents
From everything it sees to everything it does, Qwen3.8-Max is not merely capable of understanding images, documents, and videos. It delivers visual intelligence that runs through the entire task lifecycle.
When working with financial reports and complex PDFs spanning more than 200 pages, Qwen3.8-Max can understand text, charts, and document layouts across pages, extract key insights from large volumes of information, and turn them into structured reports or production-ready web experiences. When processing videos longer than 100 hours, it can do more than locate specific moments and answer detailed questions. It can organize people, events, timestamps, and scenes into a video memory graph, continuously building connections across long time spans to reconstruct event progressions, character relationships, and critical moments.
Whether the input is a hundreds-page document, a complete TV series, or a 100-hour livestream, information that would otherwise be difficult to consume can be transformed into a searchable, traceable, and interactive knowledge structure.
Beyond understanding, Qwen3.8-Max can carry out real visual production tasks. It can edit personal footage into a vlog, turn a question into an immersive educational animation, reconstruct a complete frontend project from a single interface screenshot, transform a floor plan into a Blender-based 3D interior visualization, and develop interactive games and applications from a natural-language request.
More importantly, vision is not limited to the input stage. During execution, Qwen3.8-Max continuously observes and evaluates its own intermediate results. It can inspect page layouts, object orientations, spatial relationships, animation quality, and interaction outcomes. When it detects issues—such as a television facing the wrong direction, a misaligned interface, or a visual result that does not match the intended design—it can identify the deviation, revise its plan, and correct the output autonomously.
This means vision is no longer simply another modality that an agent uses to understand input. It becomes a native feedback loop across planning, execution, verification, and iteration. The model generates while observing, acts while reviewing, and repeatedly examines the result, identifies problems, and improves its work. This visual feedback loop moves an agent beyond merely completing a task toward completing it well.
Qwen3.8-Max is helping multimodal agents evolve from understanding the world to continuously acting and creating within it through vision.
In the digital world, finishing a complex task on its own often takes two things at once: writing code to implement the underlying logic, and operating the interface by hand to drive the task and observe the result. This Hybrid Agent capability — the pairing of coding and GUI operation — makes the two channels complementary: coding does the heavy lifting efficiently and at scale, while GUI operation reaches whatever a human can see and touch and, just as importantly, feeds back what actually happens in a live system — extending the visual feedback loop above from inspecting its own output to verifying against a real, running application.
To measure this, we introduce RecreationBench, a long-horizon application-recreation benchmark spanning five platforms — desktop (Ubuntu, macOS, Windows), mobile (Android), and web. The model may observe a real, running application only as a black box — no source code, no internet access — making sense of it purely through interaction and feedback, then rebuilding the whole application from scratch. Here Qwen3.8-Max already demonstrates frontier-level Hybrid Agent capability, converging on the original step by step through repeated cycles of iterative coding and interactive feedback.
To make these capabilities easier to integrate into existing agent systems, we are also introducing Qwen-MM-Plugins. It is a harness extension library designed for multimodal agents, providing agent frameworks with image and video processing, multimodal memory, dynamic-resolution support, visual tool use, and specialized capabilities for tasks such as video editing, Blender, and CAD. With Qwen-MM-Plugins, any existing agent harness can be extended into a more naturally multimodal-native system.
User Feedback
The most honest take on Qwen3.8-Max comes from people who actually put it to work. Top-tier agent platforms, leading open-source algorithm teams, professional firms in law, finance, and manufacturing, scrappy startups, solo developers, and academic researchers — all of them keep handing it their most complex, mission-critical, and long-horizon tasks.
Enterprises use it to stand up large-scale agent systems. Knowledge workers dump their images, manuscripts, and video on it, and get everything processed. Developers hand it their heaviest engineering tasks outright. Research teams run the loop of literature, data, and simulation end to end. One model, reached for so often across such different work that it becomes indispensable. The verdict is the same: Qwen3.8-Max drives long, autonomous task chains and turns out ship-ready results in a single pass.
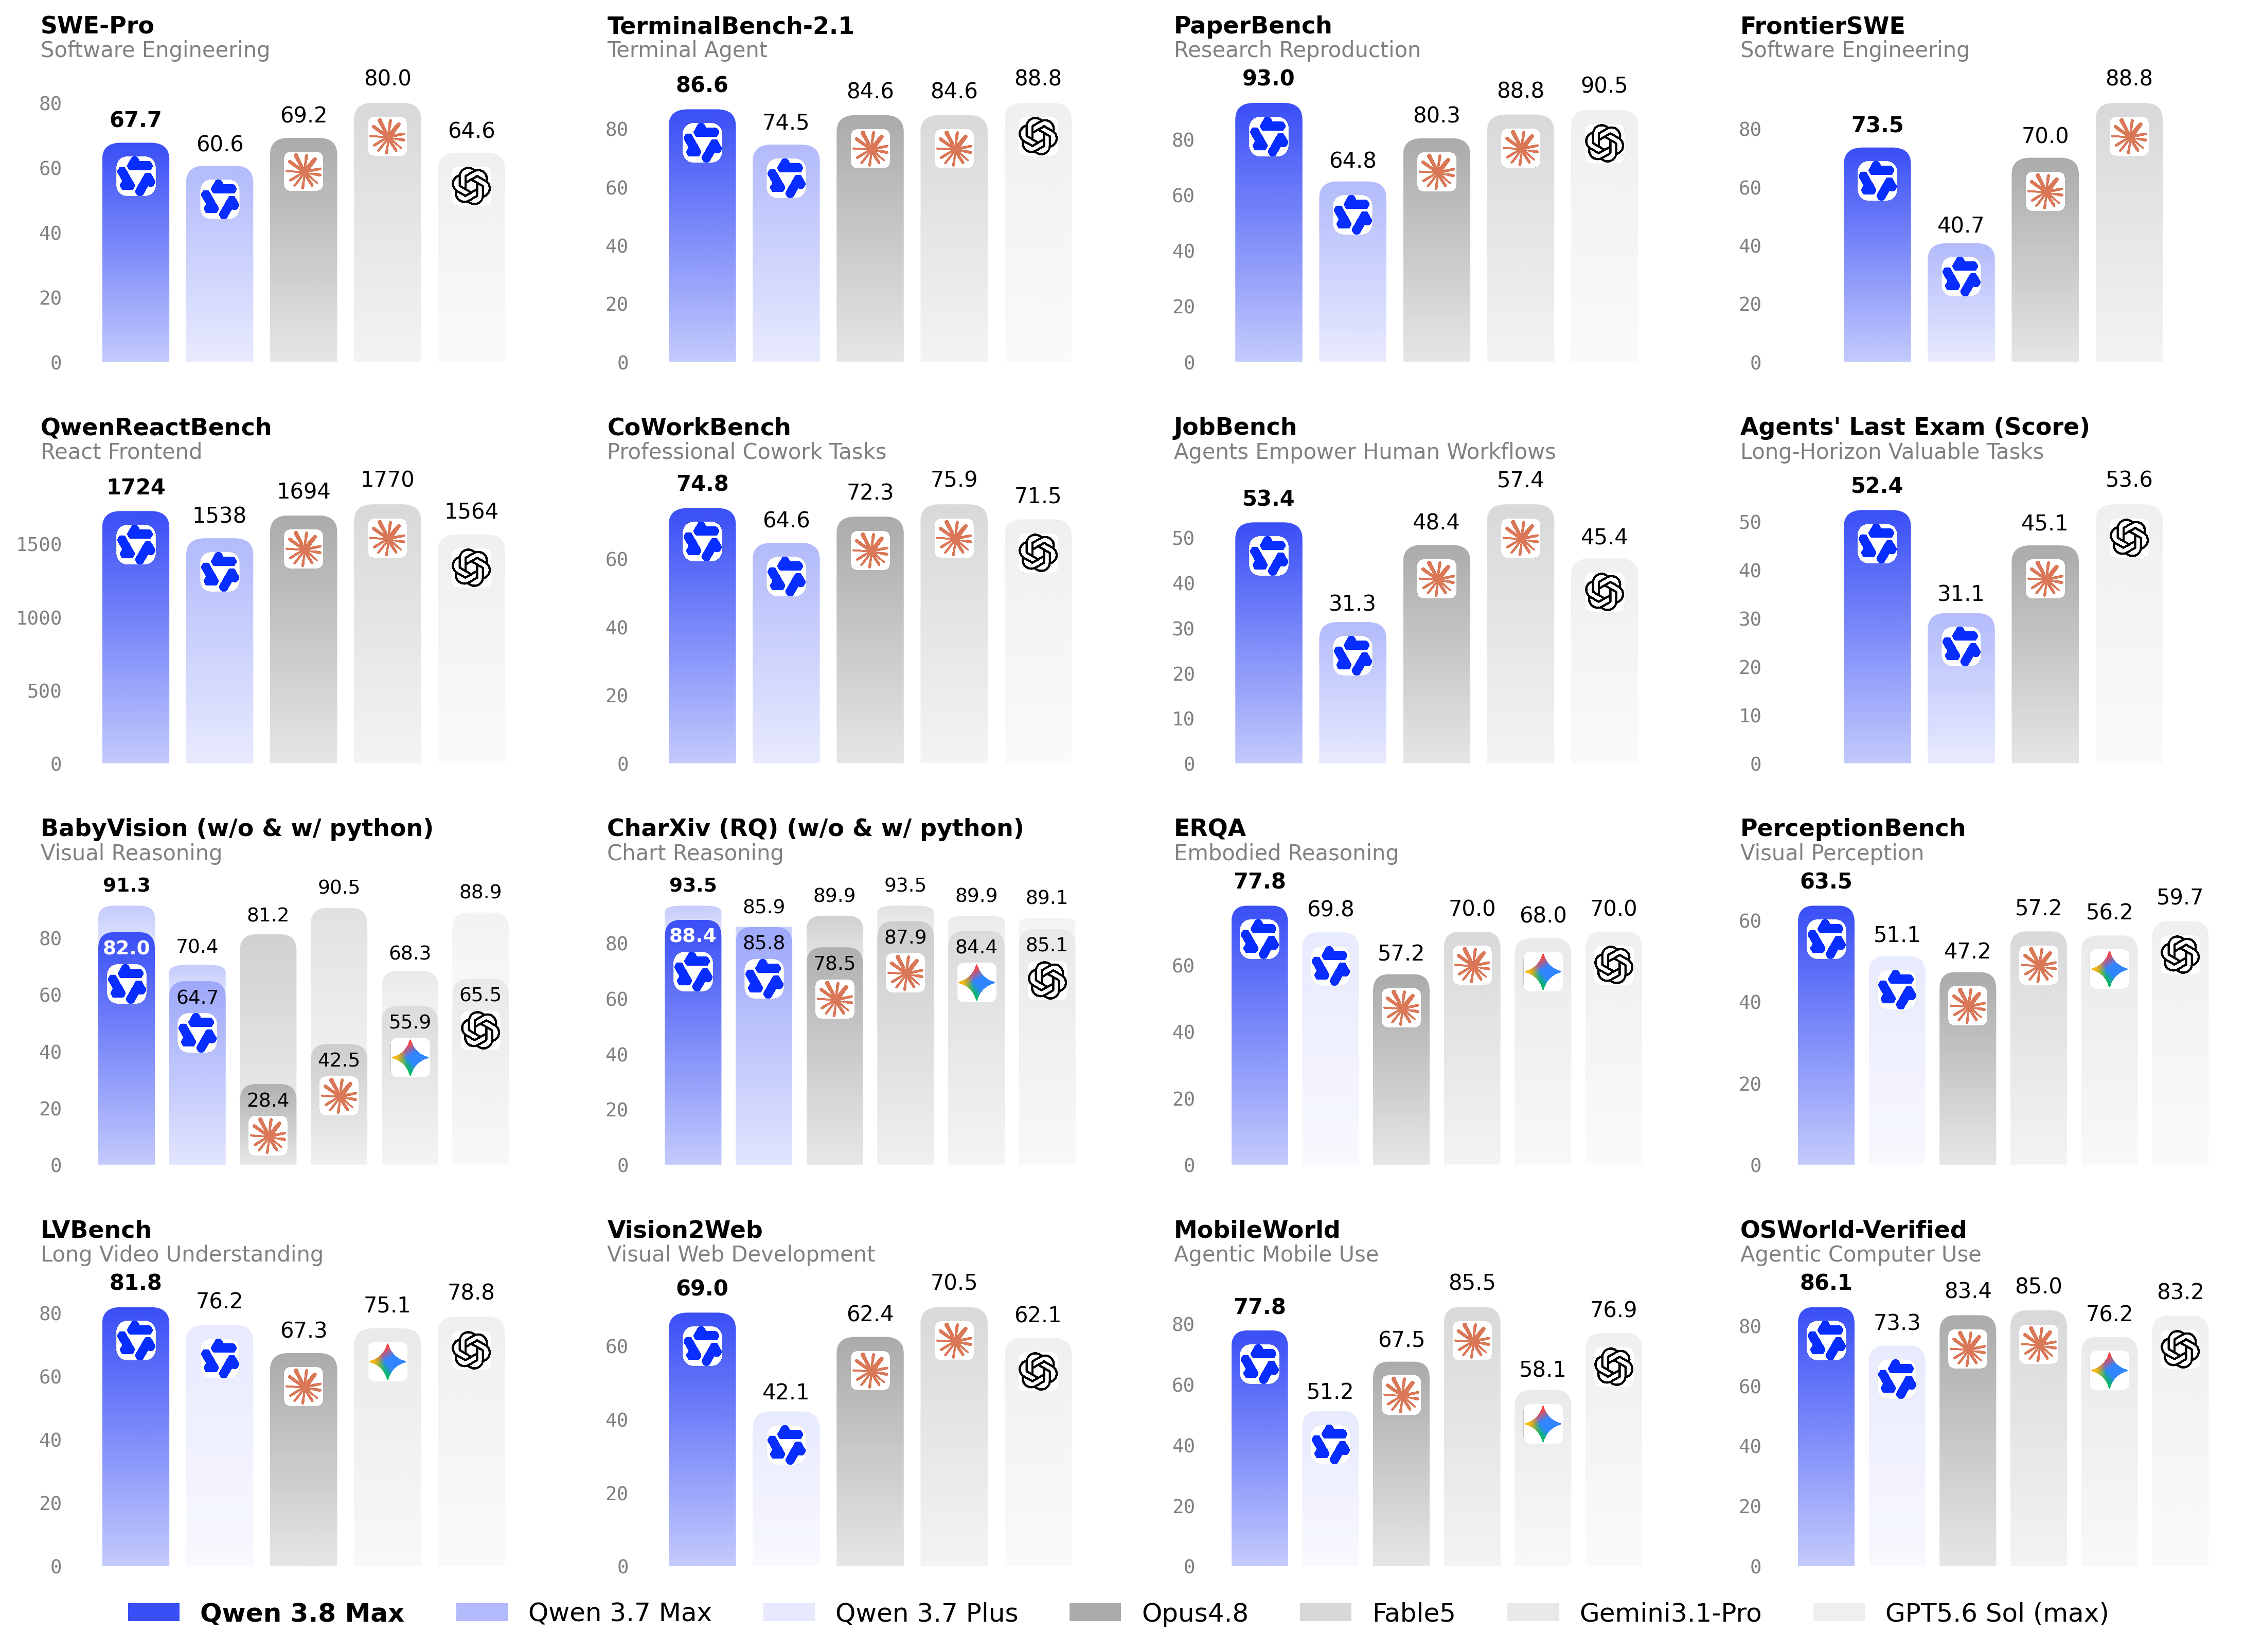
Full Benchmark Table
Opus4.8
Fable5
GPT5.6 Sol (max)
Qwen3.7-Max
Qwen3.8-Max
Coding Agent
Terminal Bench 2.1
84.6
84.6
88.8
74.5
86.6
SWE-bench Pro
69.2
80.0
64.6
60.6
67.7
DeepSWE 1.1
59.0
70.0
73.0
21.6
56.6
NL2Repo-Bench
69.4
—
—
47.2
55.9
FrontierSWE
70.0
88.8
—
40.7
73.5
MLS-Bench-Lite
42.8
49.9
46.2
31.7
41.0
PaperBench
80.3
88.8
90.5
64.8
93.0
AndroidBench
69.8
84.5
74.0
56.5
75.1
QwenSWEBench
84.0
86.3
73.5
63.4
80.7
QwenQoderBench
62.7
63.1
53.8
36.8
58.4
QwenReactBench
1694
1770
1564
1538
1724
QwenSVGBench
1648
1690
1758
1499
1713
General Agent
CoWorkBench
72.3
75.9
71.5
64.6
74.8
WorkSpaceBench
66.8
68.7
65.6
61.4
67.7
JobBench
48.4
57.4
45.4
31.3
53.4
SkillsBench
65.1
70.9
73.5
61.2
70.2
Agents’ Last Exam (Pass / Score)
27.0 / 45.1
— / —
30.6 / 53.6
11.8 / 31.1
27.0 / 52.4
Automation-Bench (Pass@1)
27.2
29.1
29.7
14.2
27.3
Toolathlon Verified (Pass@1)
76.2
77.9
74.9
49.7
72.5
WideSearch
72.9
81.2
—
75.2
81.9
HLE w/ tools
57.9
64.5
58.0
53.5
56.2
General Capabilities
GPQA Diamond
92.0
92.6
94.1
92.4
92.6
HLE
45.7
53.3
47.2
41.4
43.6
IFBench
62.2
63.5
72.7
79.1
82.8
$OneMillion-Bench (expert score)
41.8
55.9
53.8
44.4
52.5
HealthBench
52.4
—
55.3
54.5
60.2
PLawBench
69.6
70.2
72.3
58.9
73.2
PRBench-Legal
52.7
57.6
57.6
48.5
57.6
PRBench-Finance
51.9
55.8
55.5
46.8
58.3
MRCR v2 256K (8-needle)
83.2
—
93.8
86.7
92.9
LongBench v2
69.1
—
67.1
65.3
66.3
1. Fable5 results may involve fallbacks. 2. Terminal Bench 2.1: Evaluated with Claude Code (avg@10), using a 5-hour timeout and max_tokens=131,072. For all other models, we report the best published score across harnesses: Claude Opus 4.8 and Claude Fable 5 with Terminus 2 from Artificial Analysis (https://artificialanalysis.ai/evaluations/terminalbench-v2-1); GPT-5.6 Sol with Codex (https://openai.com/index/previewing-gpt-5-6-sol/). 3. SWE-bench Pro: Evaluated with the Claude Code harness, temp=1.0, top_p=0.95, and a 256K context window. Problematic tasks corrected and all baselines evaluated on the refined benchmark. 4. DeepSWE 1.1: Evaluated with the Claude Code and mini-SWE-agent harnesses, temp=1.0, top_p=0.95, and a 256K context window. We report the highest score among both harnesses; notably, Qwen3.8-Max performs best on Claude Code. 5. NL2Repo-Bench: Evaluated with the Claude Code harness. To prevent reward hacking, we disable Bash commands that attempt to access the specific repository, such as pip download, pip install, and git clone. 6. FrontierSWE: Evaluated with the Claude Code harness. All other available MEAN@5 results are taken from the official FrontierSWE leaderboard (https://www.frontierswe.com) as of August 3, 2026. Dominance scores are recomputed from the raw scores using the official evaluation script. “–” indicates that no official MEAN@5 result was available as of that date. 7. MLS-Bench-Lite: Evaluated with Claude Code using a 5-hour timeout and max_tokens=131,072. All other model scores are taken from the official leaderboard. 8. PaperBench: Evaluated in the BasicAgent setting under Code-Dev mode, judged by Claude Opus 4.6, and averaged over 3 runs (max 12 hours per run). 9. AndroidBench: Evaluated on the 95-task public subset, reporting avg@3 scores. 10. QwenSWEBench: Inhouse coding benchmark to evaluate models’ software engineering capabilities. Evaluated with the Claude Code harness. Reporting avg@3 with an 8-hour timeout, max_tokens=32,768, temperature=1.0, and a 256K-token context window. 11. QwenQoderBench: Inhouse coding benchmark to evaluate user experience on Qoder. Evaluated with the Claude Code harness. Reporting avg@5 with a 6-hour timeout, max_tokens=32,768, temperature=1.0, and a 256K-token context window. 12. QwenReactBench: Inhouse React project building benchmark using Claude Code as the harness, bilingual (EN/CN), 7 categories; auto-render + multimodal judge; BT/Elo rating. 13. QwenSVGBench: Inhouse SVG code generation benchmark; bilingual (EN/CN), auto-render + multimodal judge; BT/Elo rating. 14. CoWorkBench: Inhouse cowork benchmark for evaluating long-horizon tasks across computer science, finance, law, medical, and other productivity domains. 15. SkillsBench: Evaluated on the public SkillsBench v1.1 benchmark across 87 tasks, reporting the average score over three runs per task. Opus 4.8 and Fable 5 are evaluated on Claude Code; GPT-5.6 Sol is evaluated on Codex; the Qwen-series are evaluated on OpenCode. All results are from our own testing. 16. Automation-Bench: Evaluated on the 600-task public subset. 17. WideSearch: Evaluated with the Claude Code harness for external models and the Qwen-Agent harness for ours, reporting the average item-F1 over four runs. 18. $OneMillion-Bench: Evaluated using gemini-3.1-pro-preview. 19. PLawBench: Evaluated using gemini-3.1-pro-preview. 20. Empty cells (–): Scores are not yet available or are not applicable.
Opus4.8
Fable5
Gemini3.1-Pro
GPT5.6-Sol
Qwen3.7-Plus
Qwen3.8-Max
Multimodal Reasoning
MMMU-Pro
75.6
81.2
80.5
83.0
79.0
82.3
MathVision
87.1 / 97.1
92.7 / 98.6
87.4 / 95.7
90.8 / 97.8
90.3 / —
95.2 / 97.7
BabyVision
28.4 / 81.2
42.5 / 90.5
55.9 / 68.3
65.5 / 88.9
64.7 / 70.4
82.0 / 91.3
HLE-VL (w/ Tools)
—
—
43.9
51.2
25.6
52.2
ZeroBench (Pass@5)
17.0 / 34.0
20.0 / 46.0
17.0 / 23.0
22.0 / 35.0
19.0 / 19.0
24.0 / 49.0
ZeroBench-Sub
31.1
37.1
36.5
46.7
41.0
48.5
LogicVista
76.7
85.7
82.6
89.7
84.3
91.9
HiPhO
69.3
78.6
85.4
86.8
84.1
90.0
PhyX
54.2
71.7
79.4
79.1
80.0
83.5
SLAKE
75.9
86.6
82.9
85.1
83.2
90.8
MedXpertQA-MM
71.7
80.0
80.7
81.5
71.0
80.4
PMC-VQA
59.2
63.2
62.5
62.3
63.4
66.2
Visual Agent & Coding
OSWorld-Verified
83.4
85.0
76.2
83.2
73.3
86.1
OSWorld 2.0
20.6 / 54.8
— / 66.1
7.8 / 30.6
— / 62.6
2.8 / 21.5
19.4 / 46.7
ScreenSpot Pro
82.3
87.3
68.1
81.3
79.0
84.5
WebArena-Verified
67.9
71.3
64.3
69.7
55.3
66.8
AndroidWorld
75.0
88.8
70.7
77.6
81.0
85.3
MobileWorld
67.5
85.5
58.1
76.9
51.2
77.8
ClawEval-MM
73.3 / 73.8
81.2 / 77.5
50.5 / 55.2
81.2 / 78.9
57.4 / 60.1
77.2 / 74.8
Vision2Web
62.4
70.5
—
62.1
42.1
69.0
QwenBlenderBench
62.4
69.5
23.0
68.6
41.5
69.9
Parametric CAD Bench
85.1
87.5
73.5
86.2
73.8
91.5
RecreationBench
48.0
56.1
16.2
47.6
30.2
51.7
PresentBench
80.9
79.8
55.4
82.9
65.7
79.6
Document & Office Intelligence
CharXiv (RQ)
78.5 / 89.9
87.9 / 93.5
84.4 / 89.9
85.1 / 89.1
85.8 / 85.9
88.4 / 93.5
OmniDocBench 1.5
86.5
89.5
90.0
86.7
91.4
92.1
OCR-Bench-V2 (EN/ZH)
53.9 / 55.3
65.3 / 58.1
64.6 / 58.2
69.0 / 57.3
70.7 / 67.1
74.2 / 68.3
CC-OCR-Bench-V2
60.3
72.4
68.9
68.0
72.7
79.6
MTVQA-Test
48.1
41.6
54.3
52.7
51.2
56.6
MADQA
86.8
86.0
81.1
87.8
87.1
91.8
QwenVisualOffice
34.5
32.4
39.6
29.5
32.4
44.6
Real-World & Spatial Understanding
RealWorldQA
76.6
85.9
83.5
83.7
86.9
88.0
ERQA
57.2
70.0
68.0
70.0
69.8
77.8
LingoQA
73.8
77.4
66.8
72.6
83.4
84.8
SURDS
62.2
79.4
64.0
63.0
77.2
77.8
Visual Perception & Grounding
SimpleVQA
67.3
73.4
73.1
66.6
70.3
75.0
WorldVQA
33.9
53.5
54.0
45.1
43.9
53.2
MMStar
76.7
80.5
84.0
82.5
83.2
85.9
PerceptionBench
47.2
57.2
56.2
59.7
51.1
63.5
CountQA
41.3
63.1
72.8
68.6
77.0
82.4
RefAdv-S
61.7
68.6
71.9
69.2
73.0
80.2
Dense200
20.8
31.1
69.7
55.3
60.7
87.0
COCO
50.7
56.4
72.4
61.2
74.2
78.7
VisFactor
30.1
54.5
39.8
62.8
42.8
60.8
VLMsAreBiased
43.8
61.2
74.1
59.8
36.6
88.3
Video Intelligence & Agents
VideoMME (w/ Sub.)
85.4
—
86.7
89.5
88.0
90.4
VideoMME v2 (w/ Sub.)
49.0
52.2
66.9
71.1
59.7
68.3
VideoMMMU
75.3
81.2
85.3
85.0
85.4
88.7
MMVU
67.4
72.0
77.9
81.2
76.6
82.4
MLVU (M-Avg)
53.4
—
84.7
87.6
87.4
90.8
TVBench
61.5
—
73.0
83.2
78.2
81.9
LVBench
67.3
—
75.1
78.8
76.2
81.8
LVBench (w/ Mem.)
84.3
90.1
—
84.2
74.5
85.6
EgoLife (w/ Mem.)
78.3
82.3
—
70.8
68.8
80.3
VideoDR (w/ Search)
65.6
77.1
—
71.3
41.0
73.2
1. MathVision, BabyVision, CharXiv (RQ), and ZeroBench: Scores are reported as “without CI / with CI.” A small number of incorrect ground-truth annotations in MathVision and CharXiv (RQ) were corrected following manual verification. 2. MathVision: Our model is evaluated using a fixed prompt, e.g., “Please reason step by step, and put your final answer within \boxed{}.” For other models, we report the higher score obtained from runs with and without the \boxed{} formatting requirement. 3. MMMU-Pro: Results for Gemini3.1-Pro and GPT5.6-Sol are taken from official model reports or system cards. All other models are evaluated in-house. 4. ClawEval-MM: Scores are reported as “Pass@3 / average score.” Pass@3 measures the percentage passed in at least one of the three trials, and average score is the mean score across the three trials. 5. Vision2Web: Scores are averaged across the frontend, webpage, and website categories, using the Claude Code harness and gpt-5.4-2026-03-05 as the judge. 6. HLE-VL (w/ Tools): Scores are evaluated with tool use, including both Code Interpreter (CI) and Search. Scores for the tool-enabled versions of Gemini3.1-Pro and GPT5.6-Sol are measured end-to-end through their official native tool-calling APIs. 7. OSWorld 2.0: Scores are reported as “binary / partial.” The binary score is the percentage of tasks receiving the full task reward, while the partial score aggregates the partial rewards obtained across all tasks. 8. ScreenSpot Pro: Scores for Opus4.8 and Fable5 are taken from official system cards. The Fable5 results refer to the corresponding Mythos Preview scores. All other models are evaluated in-house. 9. WebArena-Verified: Scores are reported using the official WebArena grader within the OSWorld scaffold. 10. RecreationBench: An internal long-horizon application-recreation benchmark for evaluating hybrid-agent capabilities across five platforms: Ubuntu, macOS, Windows, Android, and the web. 11. PerceptionBench: Scores for comparison models are taken from the benchmark’s official release report, while our model is evaluated in-house. 12. VideoMME (w/ Sub.) and VideoMME v2 (w/ Sub.): Scores are evaluated with subtitles enabled. 13. QwenBlenderBench and QwenVisualOffice: Both are internal benchmarks. 14. LVBench and EgoLife (w/ Mem.): Scores are evaluated using a memory system built with Qwen-MM-Plugins, enabling fine-grained, long-horizon video memory. 15. VideoDR (w/ Search): Scores are evaluated with access to a search tool. 16. Empty cells (–): Scores are not yet available or are not applicable.
Build with Qwen3.8
Qwen3.8-Max is now available through QwenCloud. You can integrate it with popular agent frameworks and coding assistants. The model weights will be open-sourced on Hugging Face and ModelScope next week — stay tuned.
API Usage
Qwen3.8-Max comes with the official support for reasoning_effort, which can be used to adjust reasoning depth and control cost:
xhigh (default): for complex tasks demanding thorough analysis
medium: balancing accuracy and speed
low: efficient reasoning optimizing for speed and cost
In addition, preserve_thinking is enabled by default for all workloads for best out-of-the-box experience.
QwenCloud
QwenCloud supports industry-standard protocols, including chat completions and responses APIs compatible with OpenAI’s specification, as well as an API interface compatible with Anthropic.
python"""
Environment variables:
  DASHSCOPE_API_KEY: Your API Key from https://home.qwencloud.com/
  DASHSCOPE_BASE_URL: (optional) Base URL for compatible-mode API.
    - Beijing: https://dashscope.aliyuncs.com/compatible-mode/v1
    - Singapore: https://dashscope-intl.aliyuncs.com/compatible-mode/v1
    - US (Virginia): https://dashscope-us.aliyuncs.com/compatible-mode/v1
"""from openai import OpenAIimport os
api_key = os.environ.get("DASHSCOPE_API_KEY")if not api_key:    raise ValueError(        "DASHSCOPE_API_KEY is required. "        "Set it via: export DASHSCOPE_API_KEY='your-api-key'"    )
client = OpenAI(    api_key=api_key,    base_url=os.environ.get(        "DASHSCOPE_BASE_URL",        "https://dashscope-intl.aliyuncs.com/compatible-mode/v1",    ),)
messages = [{"role": "user", "content": "Write a Python function to merge two sorted linked lists."}]
completion = client.chat.completions.create(    model="qwen3.8-max",    messages=messages,    extra_body={        "enable_thinking": True,        # "preserve_thinking": True,    },    reasoning_effort="xhigh",  # supported levels are xhigh, medium, and low    stream=True,)
reasoning_content = ""answer_content = ""is_answering = Falseprint("\n" + "=" * 20 + "Reasoning" + "=" * 20 + "\n")
for chunk in completion:    if not chunk.choices:        print("\nUsage:")        print(chunk.usage)        continue
    delta = chunk.choices[0].delta
    if hasattr(delta, "reasoning_content") and delta.reasoning_content is not None:        if not is_answering:            print(delta.reasoning_content, end="", flush=True)        reasoning_content += delta.reasoning_content
    if hasattr(delta, "content") and delta.content:        if not is_answering:            print("\n" + "=" * 20 + "Answer" + "=" * 20 + "\n")            is_answering = True        print(delta.content, end="", flush=True)        answer_content += delta.content
Qwen3.8-Max is our most capable model to date, and the first open-weight model at Max scale. Scaling to 2.4 trillion parameters, it delivers comprehensive gains across coding, real-world work, long-horizon tasks, and multimodal agents — able to take complex, open-ended goals from start to finish with minimal human involvement and produce dependable deliverables. The open weights will be released next week. We welcome community feedback and look forward to seeing what you build.
In this release we are opening the weights of Qwen3.8-Flash-Next, a multimodal MoE model that also serves as an early preview of the architecture used in Qwen4. It plays the same role that Qwen3-Next played for Qwen3.5: the hybrid Gated DeltaNet + Gated Attention design introduced at that time has since been used across the Qwen3.5, Qwen3.6, Qwen3.7 and Qwen3.8 series. We are again releasing the architectural changes early, so that the community can examine them before the full Qwen4 model family is built on top of them.
Qwen3.8-Flash-Next upgrades the model systematically along four aspects — attention, residual, embedding and optimization — improving model capability while further optimizing computational efficiency, model capacity and training stability:
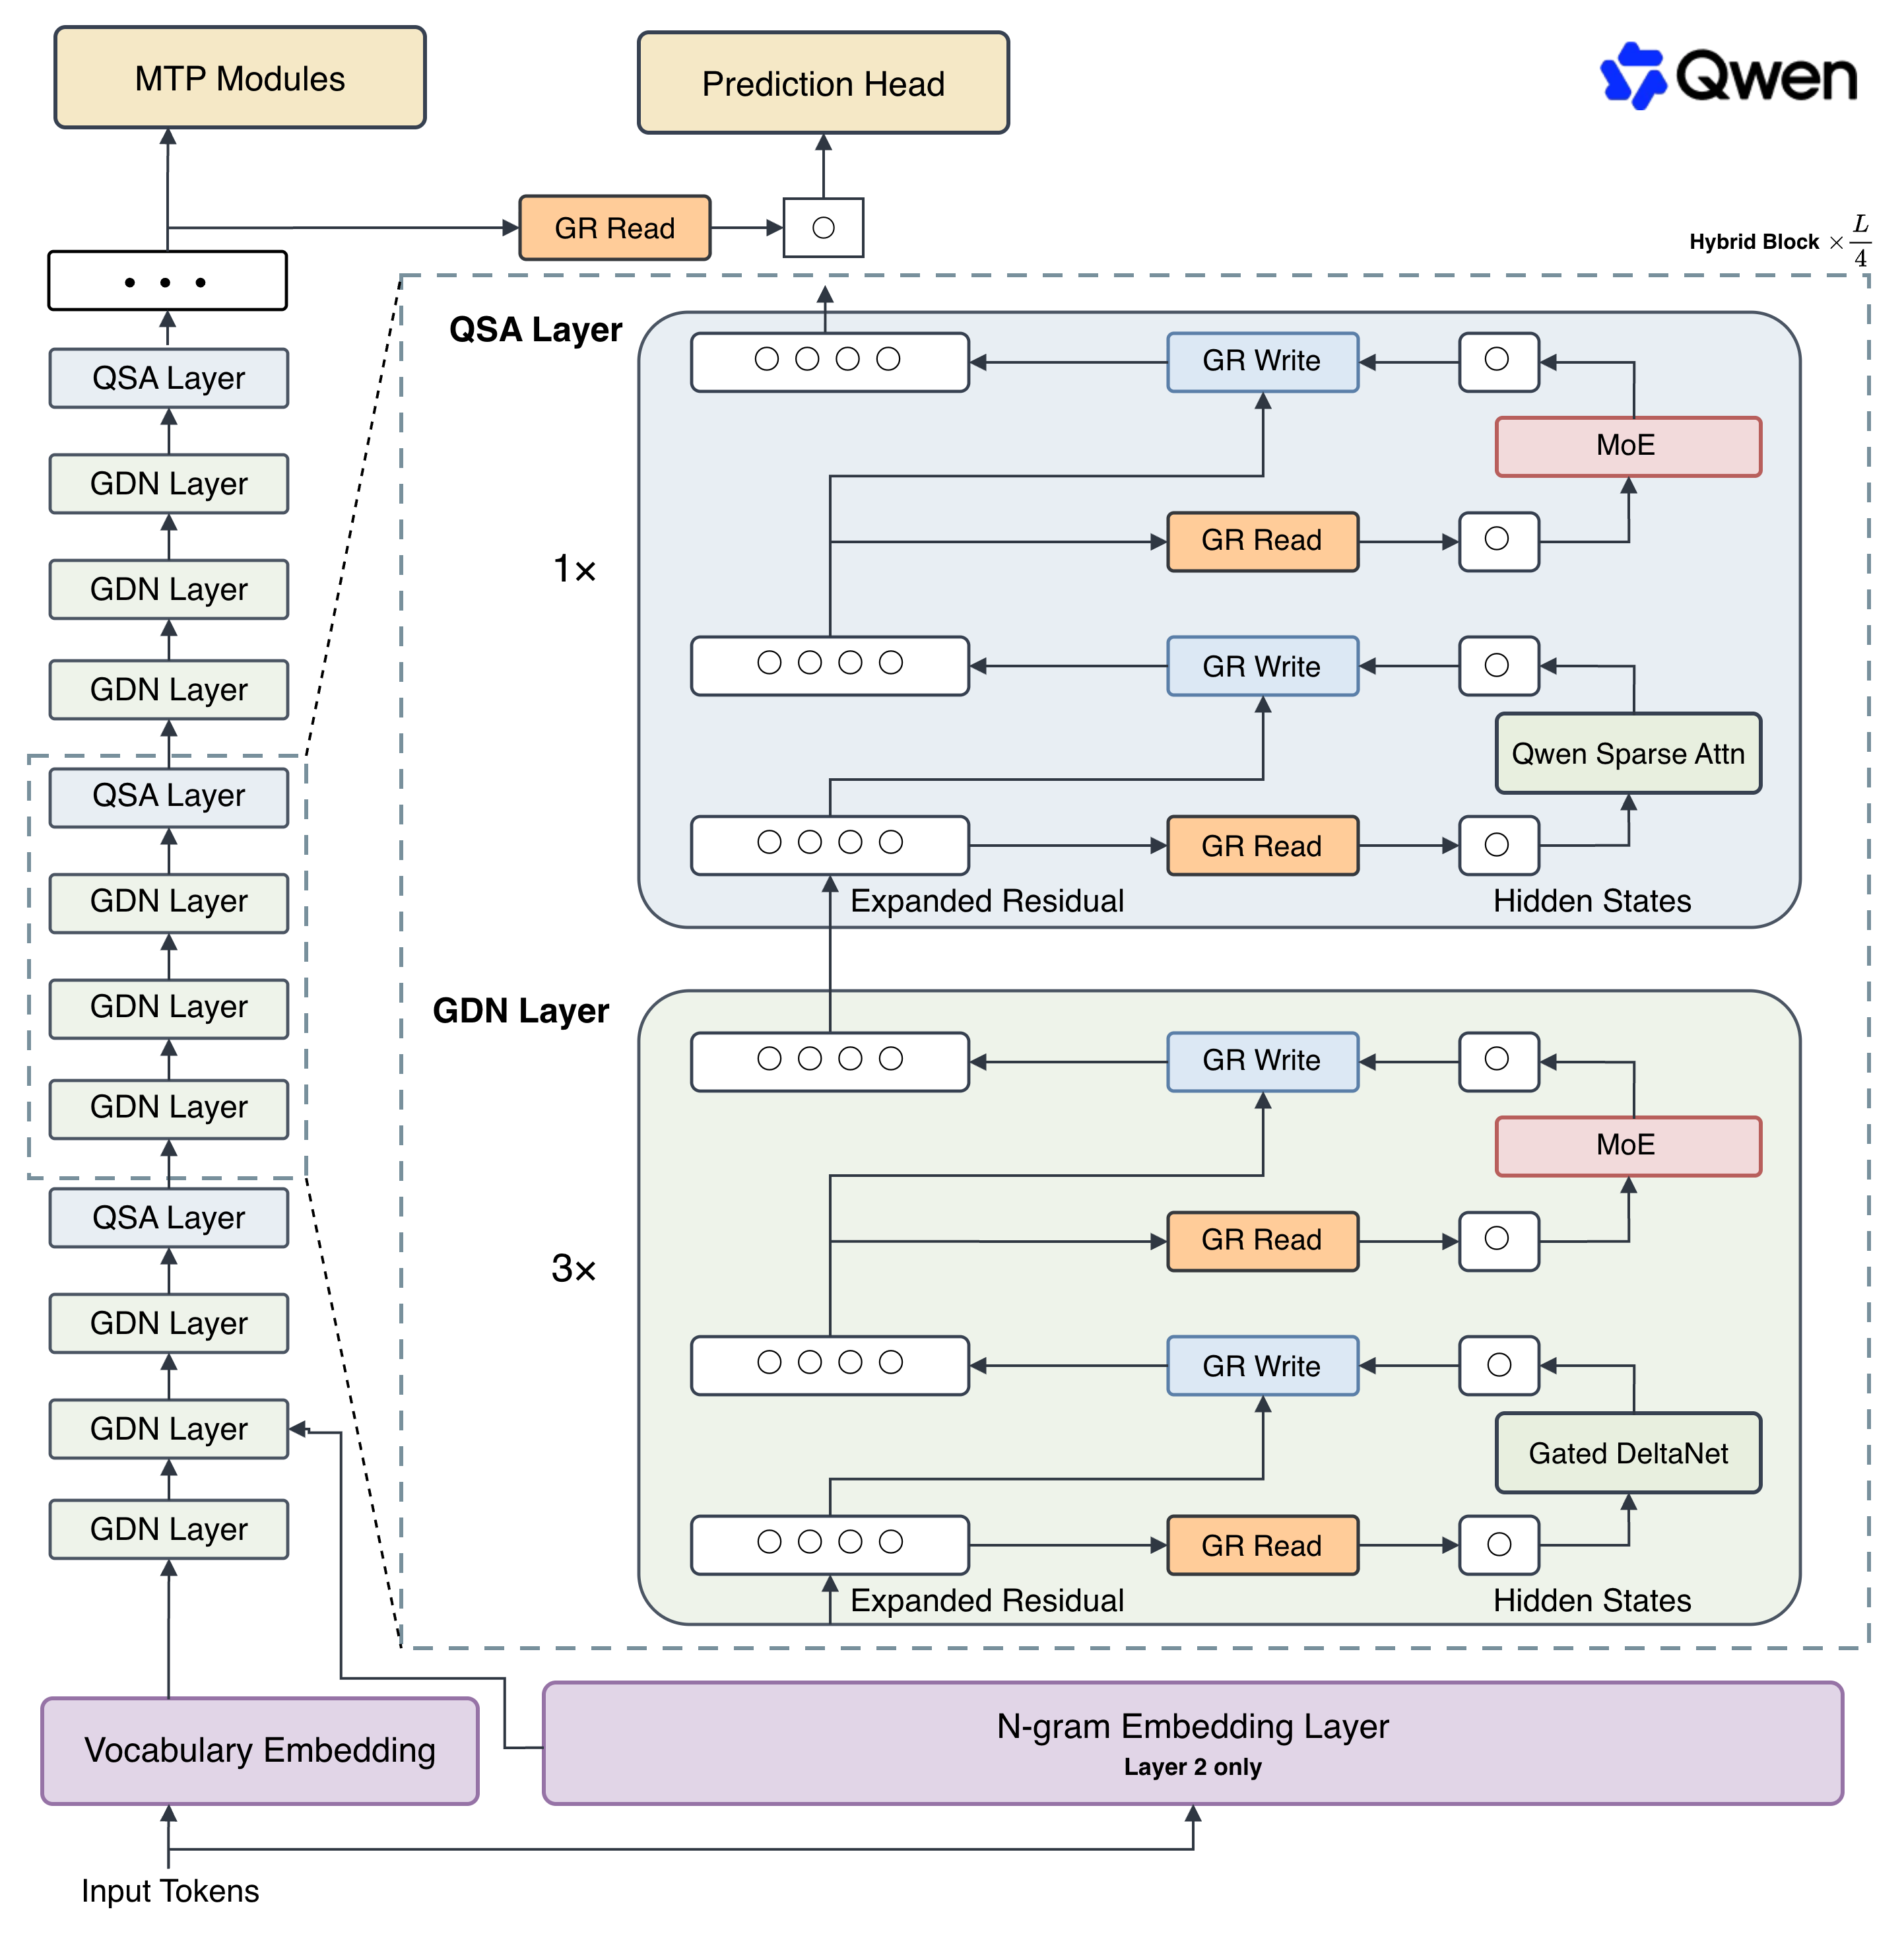
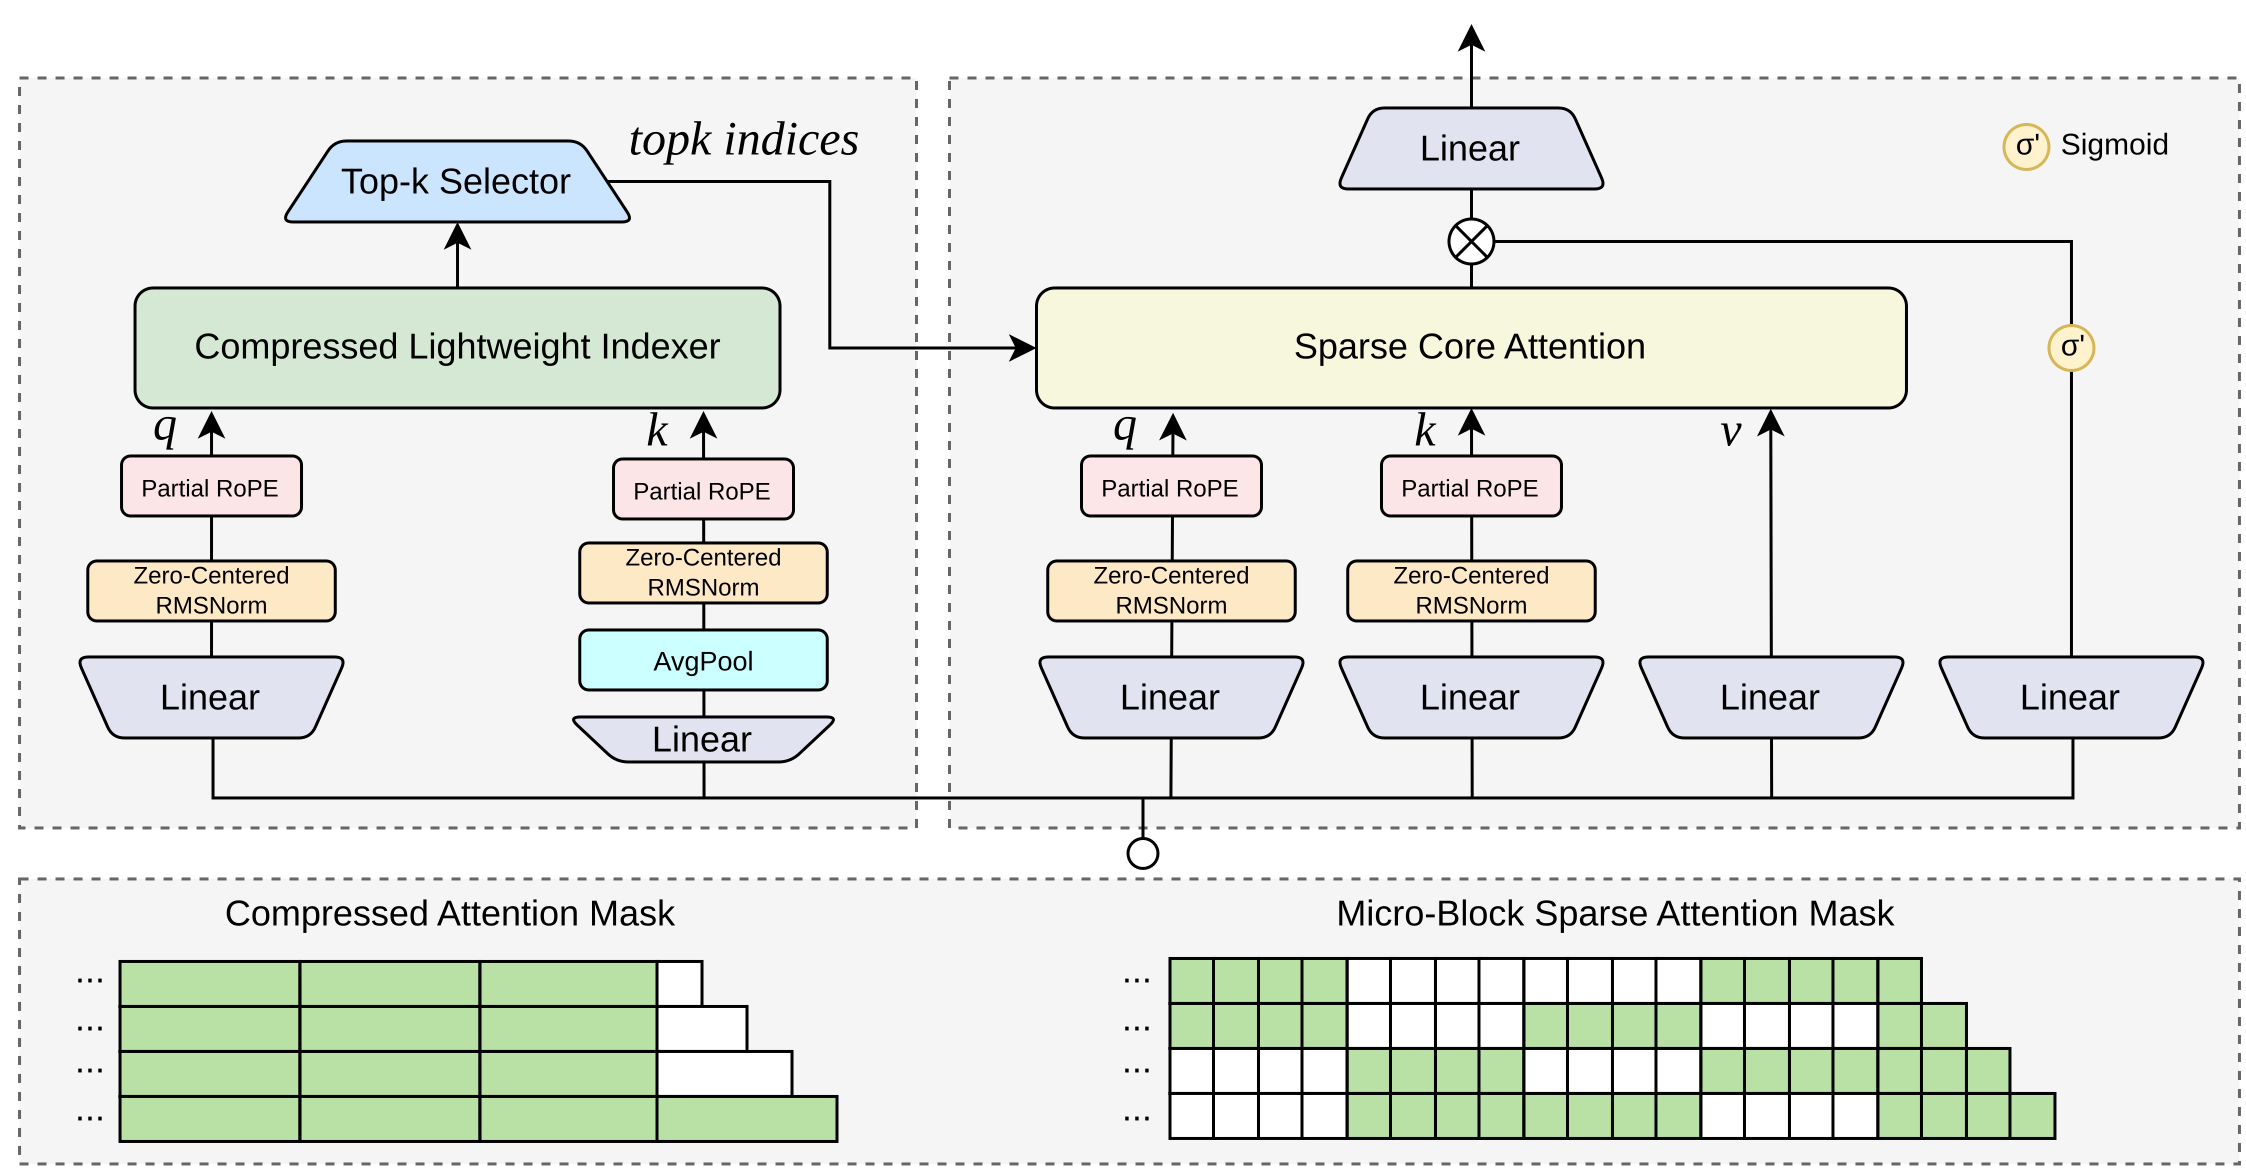
Attention: A GDN + QSA hybrid architecture. Gated DeltaNet (GDN) compresses the history efficiently; Qwen Sparse Attention (QSA) uses a compressed lightweight indexer to select the important context at micro-block granularity, substantially reducing the cost of attention on long sequences.
Residual: Gated Residual (GR) widens the residual stream into 4 branches and controls reads and writes with a dynamic gate, strengthening cross-layer information flow and training stability.
Embedding: N-gram Embedding looks up a table using the local context to scale model capacity with very little extra computation; the embedding table can be offloaded to host memory and overlapped with model computation through asynchronous prefetching.
Optimization: The Muon optimizer is used, refined around orthogonalization accuracy, the division of labour between Muon and AdamW, and the splitting of fused parameters, with the scaling law refitted for the new architecture.
Qwen3.8-Flash-Next features a 125B-parameter main model, supplemented by an additional 51B N-gram embeddings, with 6B parameters activated per token. Compared with Qwen3.7-Plus, Qwen3.8-Flash-Next substantially reduces both training and inference cost — training takes only about 1/9 as much, yet it delivers superior capabilities in coding and office tasks.
It natively supports 262,144 tokens of context and is extensible to 1,000,000 tokens with YaRN. For more technical details on the architecture, training methodology, and experimental analysis of Qwen3.8-Flash-Next, please refer to the technical report in our GitHub repository.
Qwen3.8-Flash-Next weights are now available on Hugging Face and ModelScope. The production version, with 1M context by default and official built-in tools, is served as Qwen3.8-Flash on QwenCloud, priced at 0.15 USD per million input tokens and 0.47 USD per million output tokens.
1. DeepSWE 1.1: evaluated with the Claude Code and mini-SWE-agent harnesses, temp=1.0, top_p=0.95, 256K context window. We report the highest score across the two harnesses; notably, Qwen3.8-Flash-Next performs best on mini-SWE-agent. 2. SWE-bench Pro: except for Claude-Opus-4.6 (Max), for which we report the officially published score, all models are evaluated with the Claude Code harness, temp=1.0, top_p=0.95, 256K context window. Problematic tasks were corrected and all baseline models were re-evaluated on the refined benchmark. 3. SWE-bench Multilingual: evaluated with the mini-SWE-agent harness, temp=1.0, top_p=0.95, 256K context window. 4. NL2Repo-Bench: evaluated with the Claude Code harness. To prevent reward hacking, we disable Bash commands that attempt to access the specific repository, such as pip download, pip install and git clone. 5. CoWorkBench: an in-house cowork benchmark for evaluating long-horizon office and productivity agent tasks across computer science, finance, law, medical and other productivity domains. 6. HLE: judged by GPT-4o. 7. The best result in each row is shown in bold. 8. Empty cells (–): scores are not yet available or are not applicable.
Vision Language
Qwen3.8-Flash-Next
Qwen3.8-27B
Qwen3.7-Plus
Claude-Opus-4.6 (Max)
Agentic Multimodal Intelligence
Multimodal tool useClawEval-MM
Pass@364.4Average60.4
Pass@357.4Average56.9
Pass@357.4Average60.1
Pass@352.5Average54.7
Application recreationRecreationBench
49.9
47.1
30.2
—
Mobile useAndroidWorld
84.5
81.9
81.0
62.0
Computer useOSWorld 2.0
Binary19.4Partial52.3
Binary19.4Partial48.0
Binary2.8Partial21.5
—
Visual web developmentVision2Web
64.0
62.9
42.1
—
General Multimodal Intelligence
Embodied intelligenceERQA
72.3
65.5
69.8
40.8
Long video understandingLVBench
76.6
72.4
76.2
63.0
Real-world perceptionRealWorldQA
88.5
85.9
86.9
73.9
Visual math problem solvingMathVision
Without CI90.6With CI95.7
Without CI90.0With CI94.6
Without CI90.3With CI88.7
Without CI65.5
Scientific chart analysisCharXiv (RQ)
Without CI84.6With CI90.6
Without CI83.7With CI90.2
Without CI85.8With CI85.9
Without CI66.0
1. ClawEval-MM: scores are reported as “pass@3 / average score”. Pass@3 measures the percentage passed in at least one of three trials, and the average score is the mean score across the three trials. 2. RecreationBench: an in-house long-horizon application-recreation benchmark for evaluating hybrid-agent abilities spanning five platforms — desktop (Ubuntu, macOS, Windows), mobile (Android) and web. 3. OSWorld 2.0: scores are reported as “binary / partial”. The binary score is the percentage of tasks that receive the full task reward, while the partial score aggregates the partial rewards obtained across all tasks. 4. Vision2Web: scores are reported as the average over the frontend, webpage and website categories, using the Claude Code harness and judged by gpt-5.4-2026-03-05. 5. MathVision, CharXiv (RQ): scores are reported as “without CI / with CI”. A small number of incorrect ground-truth annotations in MathVision were corrected after manual verification. Our model’s score is evaluated using a fixed prompt, e.g. “Please reason step by step, and put your final answer within \boxed{}.” For other models, we report the higher score between runs with and without the \boxed{} formatting. 6. The best result in each row is shown in bold. 7. Empty cells (–) indicate scores not yet available or not applicable.
Model Architecture
Attention: GDN + QSA for Efficient Memory and Precise Retrieval
Traditional Full Attention provides direct access to all previous tokens, but as the context grows longer, both computation and KV Cache memory-access costs increase substantially.
Following the architecture design introduced in Qwen3.5, Qwen3.8-Flash-Next adopts a GDN [1] + Attention Hybrid architecture: three out of every four layers use Gated DeltaNet (GDN) to continuously compress historical information into a fixed-size state, while the remaining layer uses global Attention for precise retrieval of information across the full context.
For global Attention, we further introduce Qwen Sparse Attention (QSA). Sparse Attention reduces long-sequence computation by attending only to important context. However, existing approaches such as DSA [2] still rely on a token-level indexer to identify important positions; as the context grows, the indexer itself becomes a non-negligible source of computation.
QSA further compresses this process: a lightweight indexer first aggregates the sequence into micro-blocks, estimates context importance at the block level, and then selects the most relevant regions for Attention. This reduces not only the cost of Attention itself, but also the indexing overhead required to identify important context. Compared with approaches that share indices across layers [3], QSA performs sequence compression independently within each layer, reducing its dependence on cross-layer Attention similarity and making it particularly well suited to Hybrid architectures where GDN and Attention layers are interleaved.
Put simply: GDN efficiently “remembers,” while QSA precisely “retrieves.”
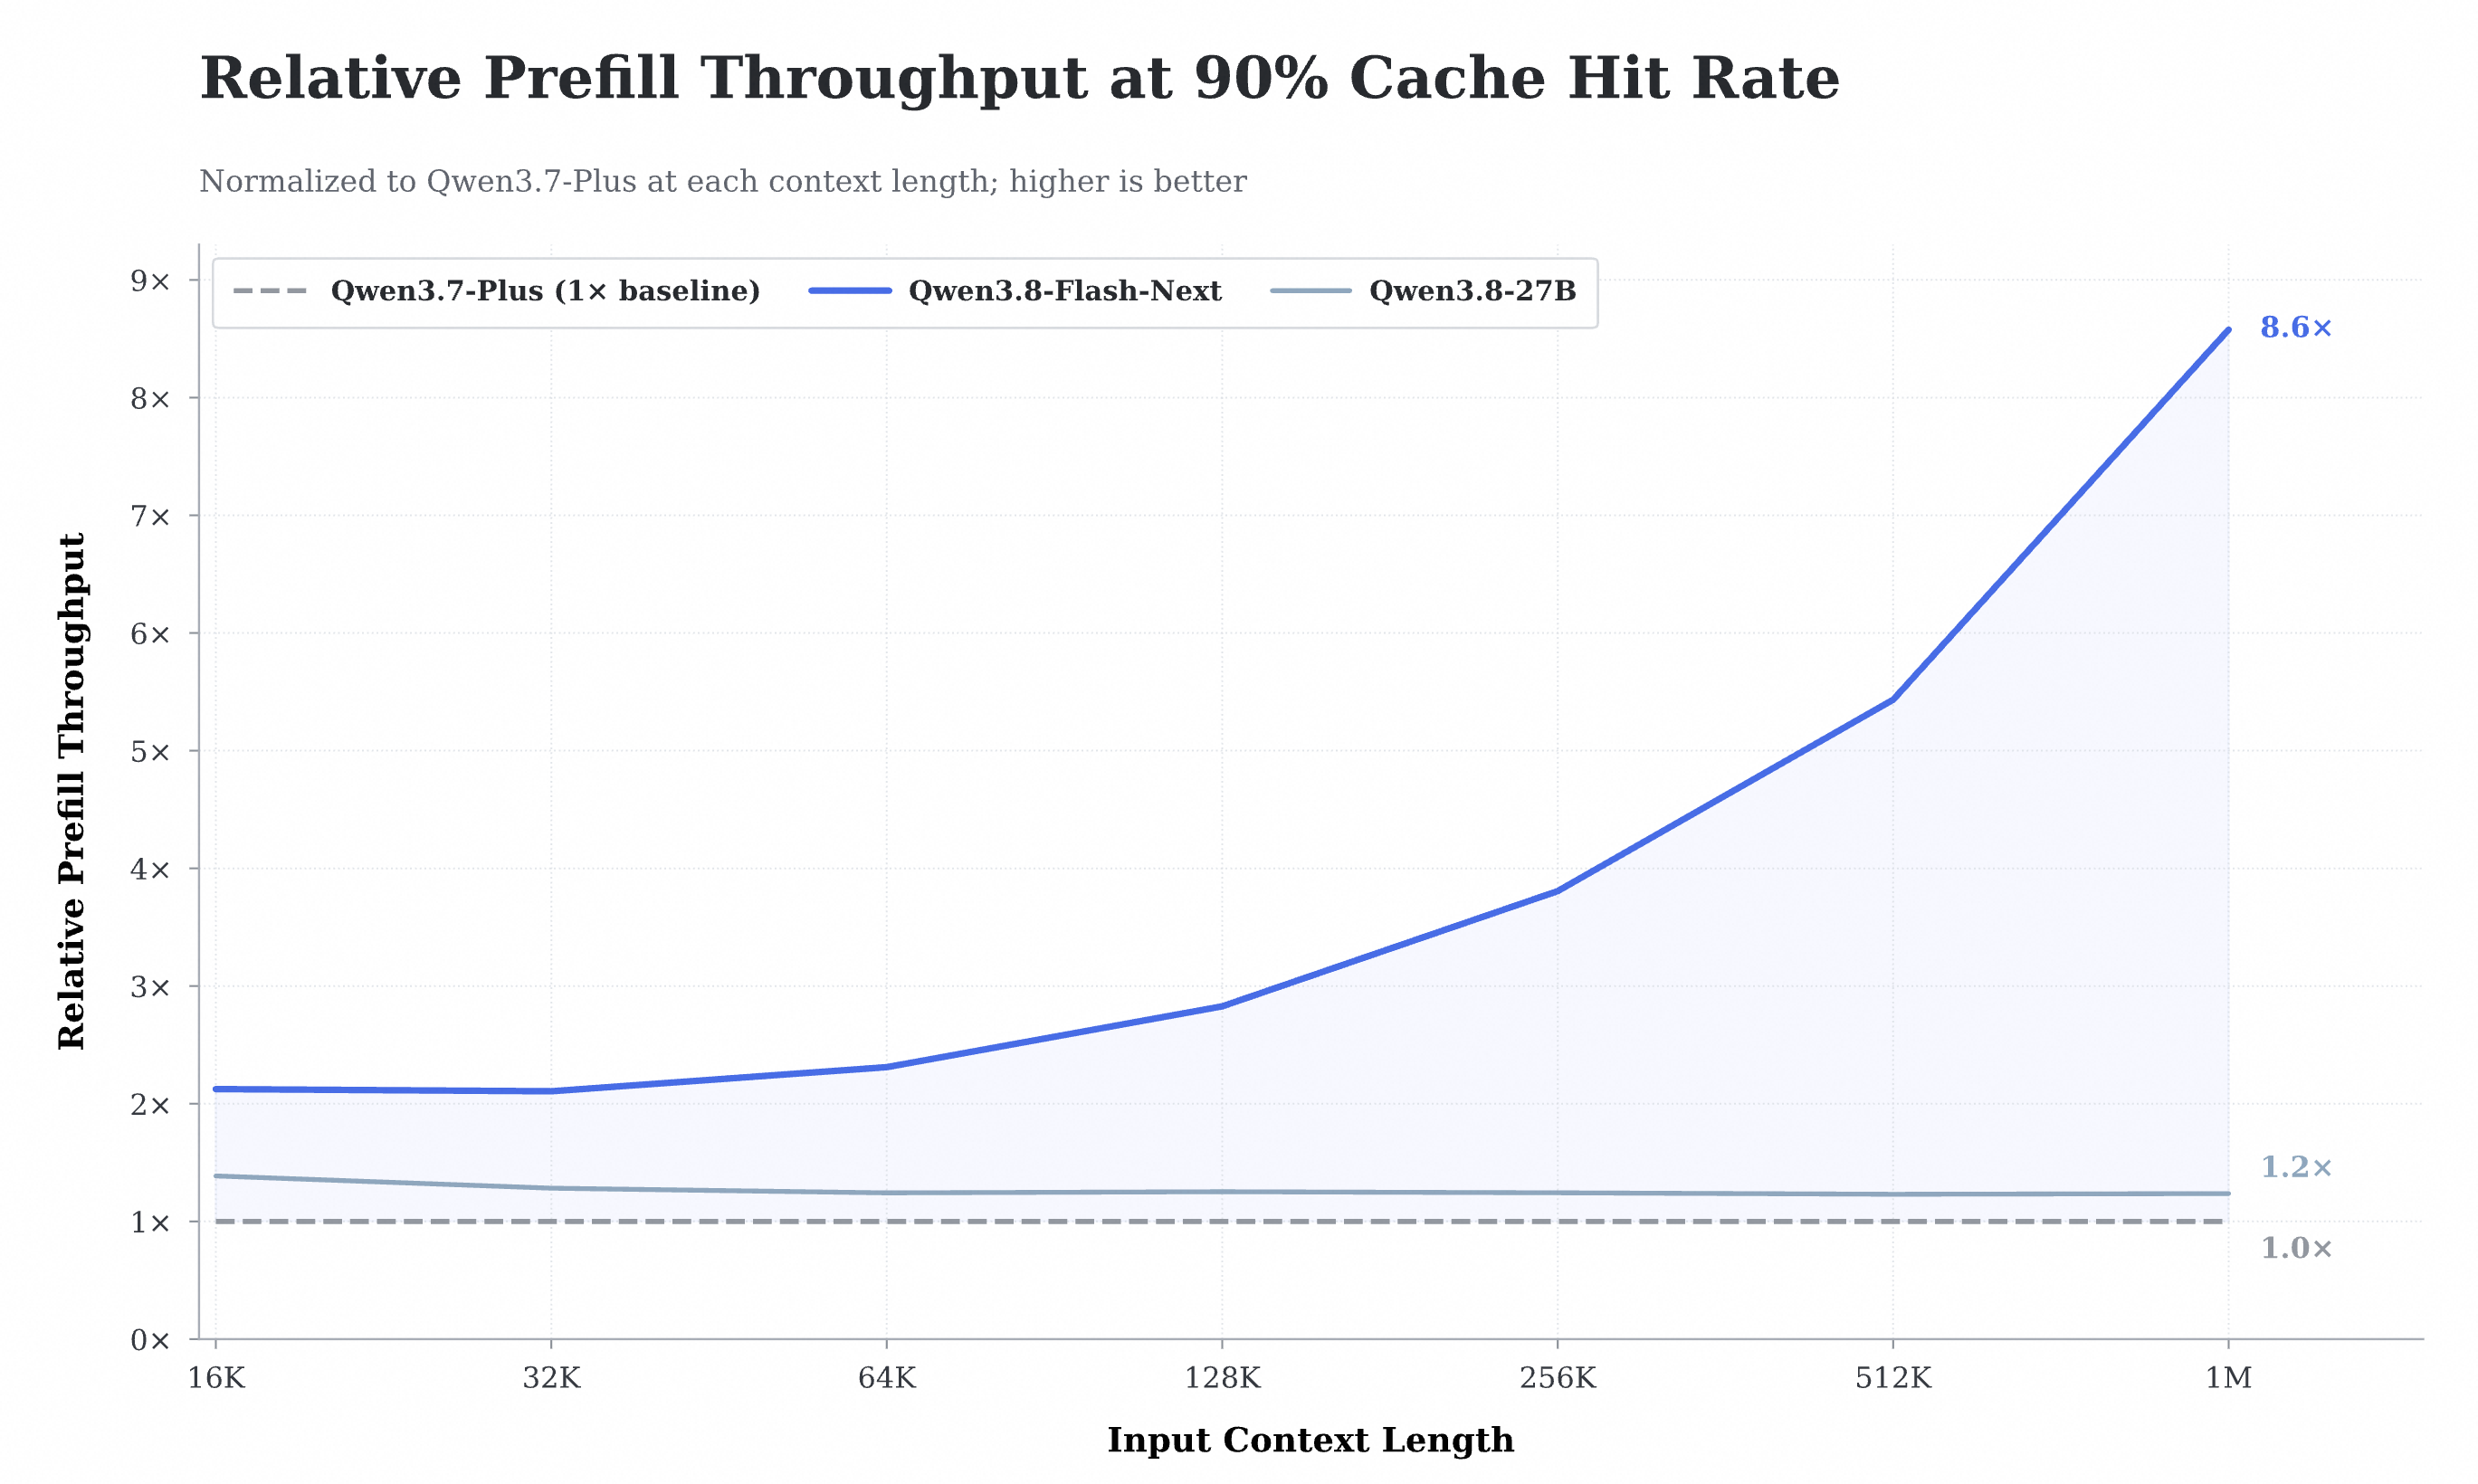
At 1M tokens, QSA’s Attention Kernel achieves up to 7.6× and 4.9× speedups in Prefill and Decode, respectively. In an experimental setup representative of online serving scenarios with high cache reuse (a 90% Prefix Cache hit rate), Qwen3.8-Flash-Next achieves 8.6× the Prefill throughput of Qwen3.7-Plus at a 1M-token context length.
Gated Residual: More Paths for Information Flow
In a traditional Transformer, all layers continuously read from and write to the same Residual Stream. As the network becomes deeper, early features are repeatedly mixed with later information, making important signals more likely to be gradually diluted.
Gated Residual (GR) can be viewed as a combination of two ideas: it follows Hyper-Connection[4] in widening the residual stream into multiple branches, while incorporating the element-wise dynamic gating of GatedNorm[5] into the residual read. The original single residual stream is expanded into four parallel branches, allowing the model to dynamically determine how much information to read from each branch and how much to write back to each branch based on the current content.
This can be conceptualized as expanding a single information channel into multiple parallel pathways: some branches handle local information flow, while others preserve early information directly deep into the network layers. Empirical analysis also reveals that one of these branches naturally emerges as a long-range pathway connecting the first Attention layer to most of the middle and subsequent layers.
GR also further simplifies Hyper-Connection. Once the read and write operations are expressive enough, additional branch mixing yields no significant benefits and can thus be directly removed, thereby reducing memory access overhead and sources of instability. The Gate also effectively suppresses activation outliers and improves training stability. In addition, the Residual State supports FP8 storage, further reducing memory-access overhead.
N-gram Embedding: Expanding Model Capacity at Low Cost
Inspired by Per-Layer Embedding in Gemma 3n and works such as DeepSeek Engram [6], we further introduce N-gram Embedding to scale model capacity beyond the parameters of the Transformer backbone.
A standard Embedding performs a lookup based on a single token. N-gram Embedding instead performs lookups using the local context formed by the current token and several preceding tokens, providing additional representations for common phrases and local patterns.
Its key advantage is that it can add a large number of parameters with almost no additional computation per token.
Qwen3.8-Flash-Next introduces an additional 51B N-gram Embedding parameters. Because lookup locations can be determined in advance, these parameters can be stored in Host Memory and asynchronously prefetched in parallel with model computation, without permanently occupying GPU memory.
The final model uses only a single N-gram Embedding layer near the beginning of the network, effectively adding a large-scale “local-pattern memory” at relatively low additional cost.
Optimization: Co-designing Architecture and Optimization
Qwen3.8-Flash-Next is trained with the Muon Optimizer[7], with further improvements around three key aspects of applying Muon to large-scale model training: orthogonalization accuracy, parameter assignment between Muon and AdamW, and splitting fused parameter matrices.
For parameters that genuinely act as two-dimensional linear maps, such as the main weights in Attention, GDN, and MoE Experts, we use Muon. Embeddings, the MoE Router, and the low-rank parameters in GR continue to use AdamW. For QKV, SwiGLU, and GDN projections that are fused in the implementation, we first split them according to the independent linear transformations they represent, and then perform orthogonalization separately.
For the new architecture and Optimizer, we refit the Scaling Law. The results show that the model can stably use larger Learning Rates and Batch Sizes, further improving convergence efficiency and large-scale parallel training throughput.
We also find that Batch Size Warmup, a common practice in large-scale model training, is no longer necessary: gradually increasing from a small Batch to the target Batch does not improve the final result, but instead requires 18.8% more optimizer steps. In the final training Recipe, we therefore start directly with the target Batch Size.
Other Architecture Optimizations
The remaining components follow the design established in Qwen3-Next and refined through the Qwen3.5–Qwen3.8 series.
Ultra-sparse MoE: With global load balancing [8], increasing total expert parameters while keeping the number of activated experts fixed steadily reduces training loss. Qwen3.8-Flash-Next therefore uses a large expert pool with a small number of routed experts per token, together with one shared expert.
Multi-Token Prediction: The MTP module is trained with multiple steps, maintaining consistency between training and inference and thereby improving the acceptance rate of speculative decoding in real scenarios, while also enhancing the performance of the backbone. Its full-attention layers are replaced with QSA as well.
Training stability: Zero-centered RMSNorm with weight decay applied to norm weights, the attention output gating mechanism [9], and normalized MoE router initialization are retained. These designs make small-scale ablations more reliable and help large-scale training run smoothly.
Base Model Performance
We compare Qwen3.8-Flash-Next-Base with the base models of Qwen3.8-27B and Qwen3.7-Plus.
Qwen3.8-Flash-Next-Base
Qwen3.8-27B-Base
Qwen3.7-Plus-Base
# Params
125B
27B
397B
# Activated params
6B
27B
17B
# N-gram embedding params
51B
—
—
General tasks
MMLU
90.36
87.51
90.43
MMLU-Redux
90.68
87.26
91.47
MMLU-Pro
73.23
68.60
70.90
SuperGPQA
51.36
44.86
48.42
BBH
90.87
89.56
89.41
Math & STEM tasks
GPQA
51.42
45.01
51.52
GSM8K
93.29
93.18
92.95
MATH
72.78
60.54
74.38
Coding tasks
EvalPlus
78.76
76.05
78.06
MultiPL-E
79.09
74.50
81.68
SWEBench-Pretrain
50.99
41.66
49.24
Multilingual tasks
MGSM
89.33
86.37
85.42
MMMLU
84.86
79.74
84.53
INCLUDE
78.40
74.37
78.90
1. The best result in each row is shown in bold. 2. Empty cells (–): scores are not yet available or not applicable.
With 6B activated parameters, Qwen3.8-Flash-Next-Base achieves the best result on 8 of the 14 benchmarks, including MMLU-Pro, SuperGPQA, BBH, GSM8K, EvalPlus, SWEBench-Pretrain, MGSM and MMMLU, and remains close to Qwen3.7-Plus-Base on MMLU, MMLU-Redux, GPQA, MATH and MultiPL-E. The 51B N-gram embedding parameters are deterministically addressed and do not enter the per-token matrix-multiplication budget.
Develop with Qwen3.8-Flash-Next
Qwen3.8-Flash-Next is available as an open-weight model on HuggingFace and ModelScope, with official managed APIs on QwenCloud. Designed to balance capability, latency, and cost, it is well suited for high-volume applications, tool-driven workflows, and coding & coworking assistants. In the following, you can explore how to call the QwenCloud API and integrate Qwen3.8-Flash-Next into agentic systems and coding assistants.
API Usage
Qwen3.8-Flash-Next is available via API:
QwenCloud
On QwenCloud, the model is served under the name qwen3.8-flash. QwenCloud supports industry-standard protocols, including OpenAI-compatible Chat Completions and Responses APIs, alongside an Anthropic-compatible interface.
python"""
Environment variables:
  DASHSCOPE_API_KEY: Your API Key from https://home.qwencloud.com/
  DASHSCOPE_BASE_URL: (optional) Base URL for compatible-mode API.
    - Beijing: https://dashscope.aliyuncs.com/compatible-mode/v1
    - Singapore: https://dashscope-intl.aliyuncs.com/compatible-mode/v1
    - US (Virginia): https://dashscope-us.aliyuncs.com/compatible-mode/v1
"""from openai import OpenAIimport os
api_key = os.environ.get("DASHSCOPE_API_KEY")if not api_key:    raise ValueError(        "DASHSCOPE_API_KEY is required. "        "Set it via: export DASHSCOPE_API_KEY='your-api-key'"    )
client = OpenAI(    api_key=api_key,    base_url=os.environ.get(        "DASHSCOPE_BASE_URL",        "https://dashscope-intl.aliyuncs.com/compatible-mode/v1",    ),)
messages = [{"role": "user", "content": "Write a Python function to merge two sorted linked lists."}]
completion = client.chat.completions.create(    model="qwen3.8-flash",    messages=messages,    extra_body={        "enable_thinking": True,        # "preserve_thinking": True,    },    reasoning_effort="xhigh",  # supported levels are xhigh, medium, and low    stream=True,)
reasoning_content = ""answer_content = ""is_answering = Falseprint("\n" + "=" * 20 + "Reasoning" + "=" * 20 + "\n")
for chunk in completion:    if not chunk.choices:        print("\nUsage:")        print(chunk.usage)        continue
    delta = chunk.choices[0].delta
    if hasattr(delta, "reasoning_content") and delta.reasoning_content is not None:        if not is_answering:            print(delta.reasoning_content, end="", flush=True)        reasoning_content += delta.reasoning_content
    if hasattr(delta, "content") and delta.content:        if not is_answering:            print("\n" + "=" * 20 + "Answer" + "=" * 20 + "\n")            is_answering = True        print(delta.content, end="", flush=True)        answer_content += delta.content
Agent Frameworks & Coding Assistants
Qwen3.8-Flash-Next integrates seamlessly with popular agent frameworks and coding assistants:
QwenWork
QwenWork is Alibaba’s flagship AI productivity platform, designed to help individuals and enterprises automate daily tasks and accelerate operational efficiency.
We are excited to share that QwenWork has integrated Qwen3.8-Flash-Next to power its newly launched “Standard” mode, leveraging the model’s cutting-edge capabilities to deliver a seamless, cost-effective experience that sets a new standard for AI agents in the workplace.
Qwen3.8-Flash-Next extends the hybrid architecture introduced in Qwen3-Next along four directions: attention, residual, embedding and optimization. QSA compresses the sequence into micro-blocks within each layer, reducing both the attention cost and the indexing cost at long context while keeping precise retrieval. Gated Residual widens the residual stream into several parallel branches and controls reads and writes with an elementwise, data-dependent gate, improving cross-layer information flow and training stability at negligible arithmetic cost; the residual state can additionally be kept in FP8, which further reduces memory traffic. N-gram embedding scales capacity through deterministically addressed lookup memory, which can be scaled with negligible per-token computation and offloaded to host memory. On the optimization side, Muon is used as the main optimizer, with orthogonalization accuracy, parameter assignment and fused-matrix splitting as the decisive implementation choices, and the scaling law refitted for the new architecture.
We release these weights early so that the architecture can be evaluated independently by the community, as we did with Qwen3-Next, and we will continue to refine it towards Qwen4.
References
[1] Gated Delta Networks: Improving Mamba2 with Delta Rule
[2] DeepSeek-V3.2: Pushing the Frontier of Open Large Language Models
[3] IndexCache: Accelerating Sparse Attention via Cross-Layer Index Reuse