Introduction
We introduce Qwen-Drive-1.0, the first vision-language foundation model for autonomous driving that unifies 3D perception and visual question answering at the pretraining stage and further extends to motion planning, while keeping the pretrained VLM architecture entirely untouched. Built on the natively multimodal Qwen3.5-4B, it attaches two external modules. A BEV perception head serves as an explicit, inspectable 3D probe, jointly performing 3D object detection, semantic occupancy prediction, and BEV map segmentation, and a Planning Expert generates future ego trajectories through flow matching. Through staged training, we substantially boost the autonomous driving capability of a general-purpose VLM and validate it on 3D perception, driving visual question answering, and motion planning tasks, forming a unified driving vision-language model that offers a new-generation VLM base for driving-scenario adaptation.
Highlights
- Qwen-Drive-1.0 is the first vision-language foundation model for autonomous driving that unifies 3D perception and visual question answering at the pretraining stage and further extends to motion planning, while keeping the pretrained VLM architecture entirely untouched.
- An external BEV perception head serves as an explicit, inspectable 3D probe, jointly learning 3D detection, semantic occupancy prediction, and BEV map segmentation, equipping the same pretrained VLM with clear perception outputs while preserving highly competitive vision-language performance.
- A staged training and data recipe unifies cross-dataset labels, rewrites responses, filters samples for consistency, and combines driving data with general-purpose vision-language supervision, supporting domain adaptation while mitigating catastrophic forgetting.
- A Planning Expert tailored to pretrained VLM representations generates future ego trajectories with flow matching. Unified trajectory annotations enable joint training across multiple public driving datasets and yield highly competitive results across open-loop, pseudo-closed-loop, and closed-loop evaluations.
Model Architecture
Qwen-Drive-1.0 builds on the natively multimodal Qwen3.5-4B. A shared vision encoder and VLM process single-view and multi-view driving images, temporal image sequences, and general images. Without changing the pretrained architecture, two external modules read from this shared pathway. The BEV perception head builds a BEV representation from multi-view single-frame inputs and jointly performs 3D object detection, semantic occupancy prediction, and BEV map segmentation. It acts as an explicit, inspectable 3D probe, and its losses provide an additional gradient path into the shared visual pathway during joint training. The Planning Expert is a diffusion transformer tailored to VLM representations. It generates 5-second ego trajectories through flow matching, with an optional textual planning reason as condition. Perception, question answering, and planning thus reside in one pretrained VLM.
Performance
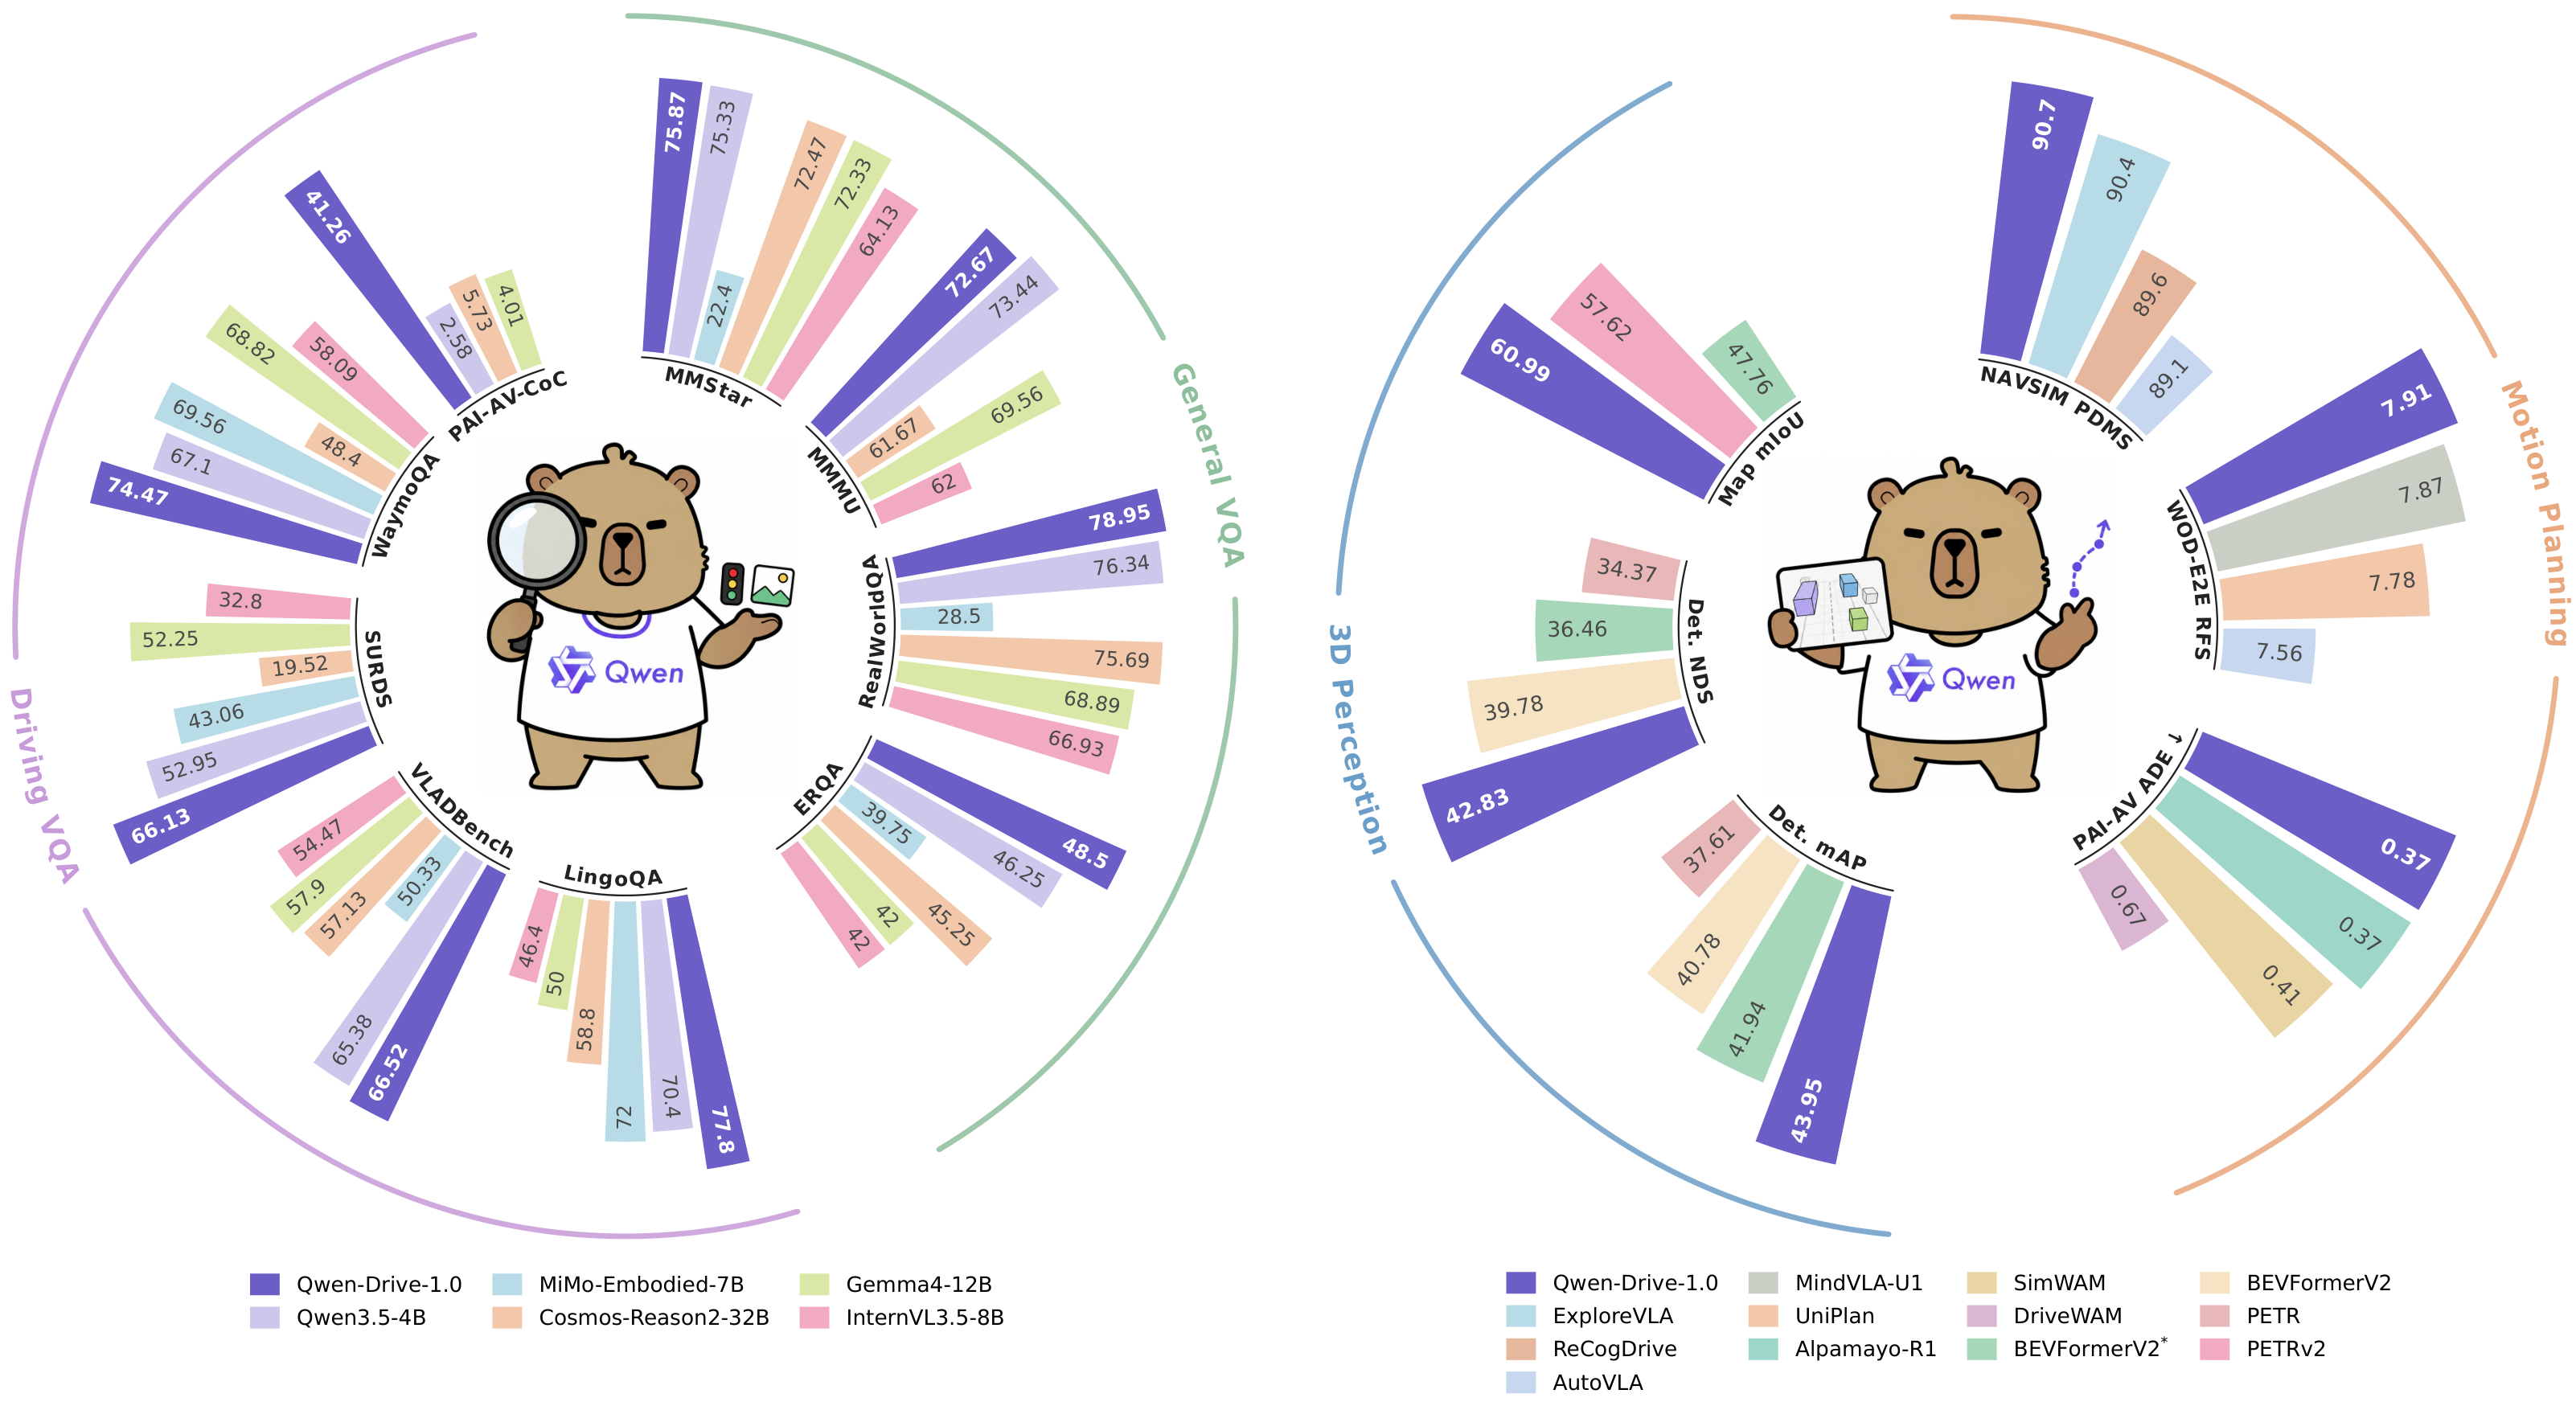
Driving Scene Understanding without Losing General Capability
Qwen-Drive-1.0-SFT reaches a driving QA average of 69.43, leading both general-purpose VLMs and driving or embodied specialists, and demonstrating its strong driving scene understanding capability.
| InternVL3.5-8B-Inst. | LLaVA-OV2-8B | Qwen3.5-4B | Cosmos-Reason2-8B | Cosmos3-nano | MiMo-Embodied-7B | Alpamayo-1.5-10B | Qwen-Drive-1.0-SFT | |
|---|---|---|---|---|---|---|---|---|
| Driving VQA | ||||||||
| LingoQA | 46.40 | 41.20 | 70.40 | 59.60 | 65.00 | 72.00 | 64.00 | 77.80 |
| Ego3D RMSE ↓ | 23.01 | 24.97 | 13.17 | 12.62 | 22.41 | 9.85 | 25.31 | 7.78 |
| VLAD | 54.47 | 58.71 | 65.38 | 56.37 | 57.73 | 50.33 | 9.13 | 66.52 |
| SURDS | 32.80 | 38.60 | 52.95 | 19.54 | 39.72 | 43.06 | 3.10 | 66.13 |
| WaymoQA Safety | 54.47 | 49.65 | 62.46 | 57.68 | 56.93 | 66.54 | 42.61 | 70.70 |
| WaymoQA All | 58.09 | 55.23 | 67.10 | 57.93 | 58.36 | 69.56 | 44.37 | 74.47 |
| CoC All | — | 0.57 | 2.58 | 1.72 | 4.01 | — | 3.44 | 41.26 |
| IH | 47.50 | 54.00 | 59.00 | 56.00 | 2.00 | 61.00 | 3.00 | 71.00 |
| Knowledge, Reasoning, and Recognition | ||||||||
| MMBench | 80.03 | 82.66 | 87.07 | 82.82 | 79.57 | — | 7.51 | 85.53 |
| MMStar | 64.13 | 64.93 | 75.33 | 65.27 | 66.67 | 22.40 | 26.13 | 75.87 |
| MMMU | 62.00 | 54.67 | 73.44 | 59.11 | 60.89 | — | 27.44 | 72.67 |
| MMMU-Pro Std | 46.42 | 36.30 | 64.86 | 36.07 | 46.36 | 27.40 | 15.61 | 62.72 |
| MMMU-Pro Vis | 42.25 | 25.95 | 61.27 | 43.53 | 40.75 | 28.09 | 13.47 | 59.71 |
| CharXiv | 41.70 | 40.10 | 65.10 | 42.50 | 42.10 | 57.50 | 1.50 | 64.40 |
| OCRBench | 83.20 | 79.30 | 86.90 | 87.00 | 85.20 | 78.80 | 3.20 | 86.40 |
| RealWorldQA | 66.93 | 71.76 | 76.34 | 67.45 | 69.67 | 28.50 | 46.93 | 78.95 |
| SimpleVQA | 40.77 | 36.68 | 47.84 | 45.25 | 44.99 | — | — | 46.12 |
| CountQA | 20.94 | 22.58 | 35.86 | 22.32 | 23.63 | 22.64 | 4.71 | 31.74 |
| Spatial Understanding and Grounding | ||||||||
| EmbSpatial | 74.20 | 78.43 | 75.99 | 77.61 | 77.88 | 45.05 | 20.58 | 78.85 |
| ERQA | 42.00 | 42.25 | 46.25 | 43.25 | 41.25 | 39.75 | 27.50 | 48.50 |
| RefSpatial | — | — | 54.51 | 51.81 | — | 2.17 | — | 50.78 |
| Omni3D | — | — | 47.40 | 32.85 | 32.26 | — | — | 45.79 |
| ODinW13 | — | — | 40.78 | 40.19 | 35.87 | — | — | 45.87 |
* All benchmarks use the same high-certainty decoding settings (greedy=false, top-p=0.001, top-k=1, temperature=0.01, repetition_penalty=1.0, presence_penalty=0.0) to more directly reflect model capability.
* LingoQA is scored with Qwen-Plus as the judge instead of the official LingoJudge, which we found to score leniently and inconsistently across scenarios. Under the official LingoJudge protocol, Qwen-Drive-1.0-SFT obtains a LingoScore of 79.4.
* The same judge scores every method on each benchmark.
* — marks an invalid or unparsable response.
Motion Planning on Open-Loop and Closed-Loop
Qwen-Drive-1.0 demonstrates outstanding performance in motion planning, both in open-loop and closed-loop settings. The training is entirely based on publicly available data, comprising a total of 2.83 million samples. Due to differences in annotation styles across various datasets, we unified the trajectory format to achieve stable 5-second trajectory predictions at 10 Hz.
| AutoVLA | SpanVLA | MindVLA-U1 | Alpamayo-1.5 | SimWAMIL | Qwen-Drive-1.0-SFT | Qwen-Drive-1.0-RL | |
|---|---|---|---|---|---|---|---|
| Open-loop | |||||||
| WOD-E2E (RFS val/test ↑) | –/7.56 | — | 8.20/7.87 | — | — | 7.95/7.78 | 8.45/7.91 |
| WOD-E2E (ADE 5s val/test ↓) | –/2.96 | — | 2.28/2.66 | — | — | 2.31/2.65 | 1.27/2.67 |
| PAI-AV (Avg. ADE 3s ↓) | — | — | — | 0.35 | 0.41 | 0.37 | 0.42 |
| PAI-AV (Avg. ADE 5s ↓) | — | — | — | 1.05 | — | 1.07 | 1.11 |
| Pseudo-closed-loop | |||||||
| NAVSIM (PDMS ↑) | 89.6 | 90.3 | — | — | 90.3 | 88.2 | 90.7 |
| NAVSIM best-of-6 (PDMS ↑) | — | — | — | — | — | 89.3 | 91.4 |
| Closed-loop | |||||||
| AlpaSim (at-fault score ↑) | — | — | — | 0.45 | 0.30 | 0.27 | 0.37 |
* AutoVLA and SimWAM train a separate model on each dataset.
* The SFT column reports Qwen-Drive-1.0-SFT conditioned on planning reasoning.
* IL denotes imitation learning.
* — indicates that the method does not report a result on the corresponding benchmark.
What’s Next
We consider Qwen-Drive-1.0 an initial step towards a vision-language foundation model for autonomous driving. Specifically, we introduce a BEV perception head as an explicit, inspectable 3D probe and a Planning Expert that generates future ego trajectories through flow matching. Through staged training, we substantially boost the autonomous driving capability of a general-purpose VLM and validate this route on 3D perception, driving visual question answering, and motion planning, forming a unified driving vision-language model that offers a new-generation VLM base for driving-scenario adaptation. Still, the consistency between textual reasoning and the generated trajectory remains to be strengthened, which we leave as a focus of future work.